Blog

10 Best Helicone Alternatives in 2026 (Post-Mintlify Acquisition)
Helicone alternatives need to replace both the observability layer and the gateway. Compare 10 platforms on what each covers and what it costs.
Dylan Cable · October 19, 2026
8 Best LiteLLM Alternatives in 2026 (Post-Breach)
Compare 8 LiteLLM alternatives for 2026, with real self-hosting costs, tier pricing, and what the March supply chain attack changed for gateway security.
Dylan Cable · October 19, 2026
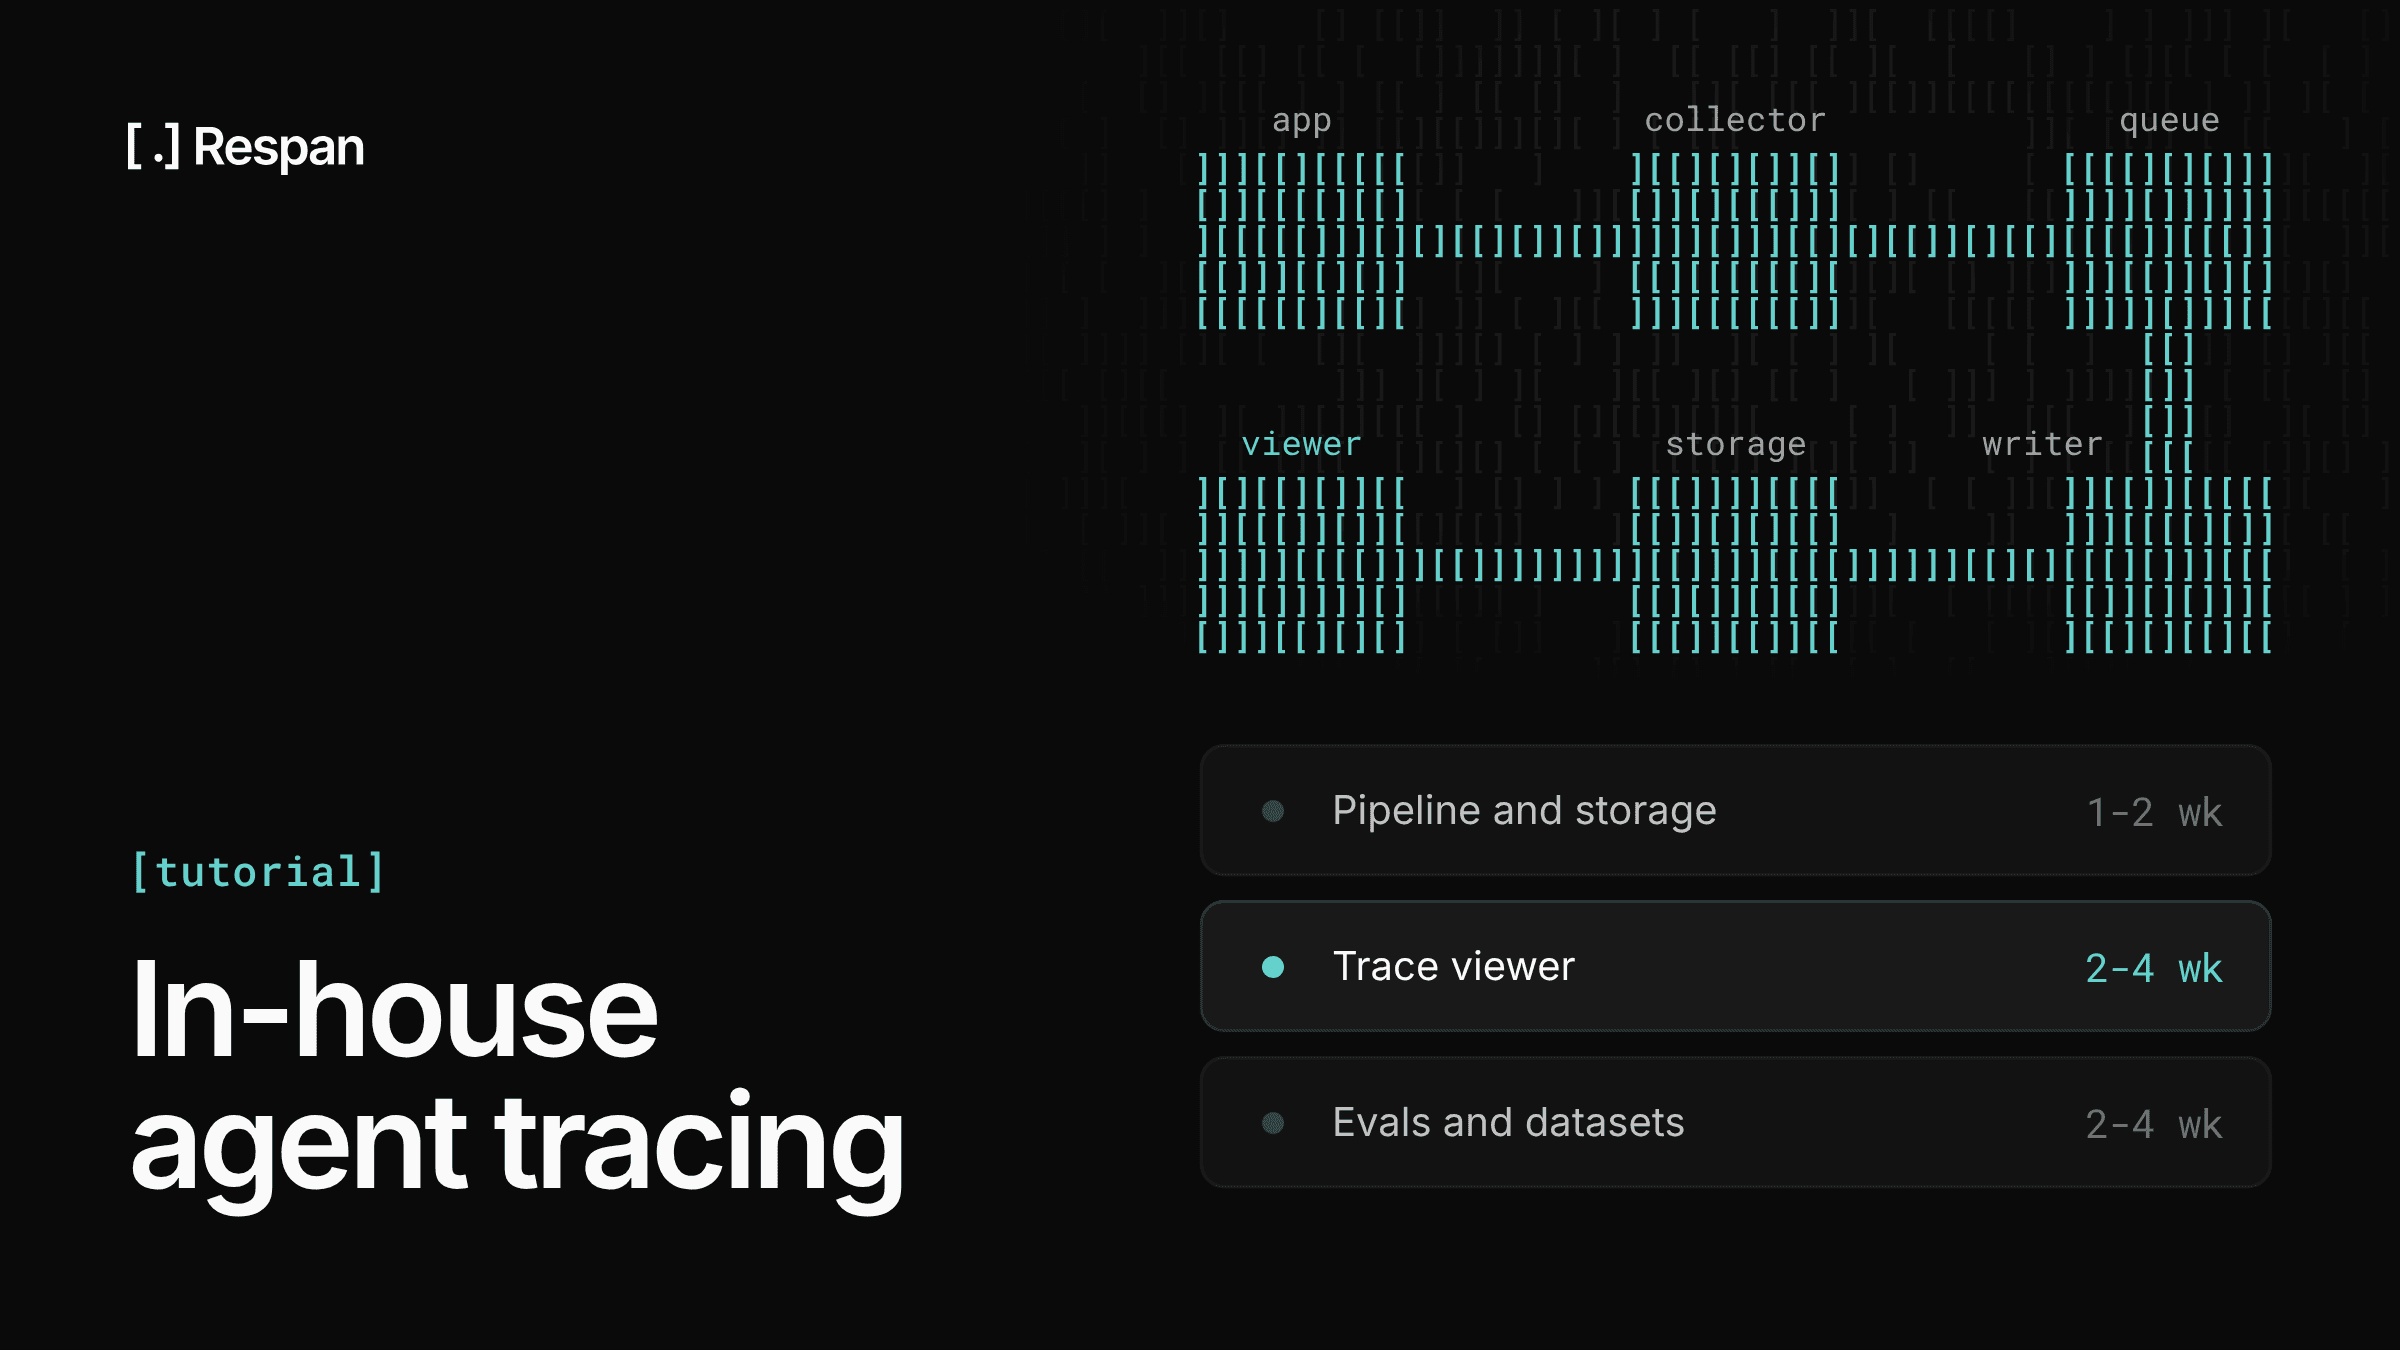
How to Build an In-House Agent Tracing System
Build an in-house agent tracing system with OpenTelemetry, ClickHouse, and object storage: data model, pipeline, trace viewer, evals, and build vs. buy.
Respan · October 16, 2026
Introducing Span-02: Anytime Reasoning for Decisions
Span-02 is an open-weight decision model with anytime reasoning. Give it a deadline and it returns its best decision so far, as probabilities over choices, yes/no, scores and numbers. It also sees images and screens.
Frank Chen · October 15, 2026
12 Best Portkey Alternatives to Replace Your LLM Gateway (2026)
Portkey alternatives matter more now that Palo Alto Networks owns it. Compare 12 LLM gateways on cutover effort and how much of Portkey each one replaces.
Dylan Cable · October 13, 2026

Error tracking in Respan
How error tracking works in Respan: error groups, fault, incidents, triage, and the span behind every error.
Frank Chen · October 13, 2026
Open Source LLMs in 2026: 10 Best Open-Weight Models, Compared
The 10 best open source LLMs of 2026, from MiMo-V2.6-Pro and Kimi K3 to Qwen3.8-27B and gpt-oss, compared by license, size, context, and public benchmarks.
Hendrix Liu · October 12, 2026
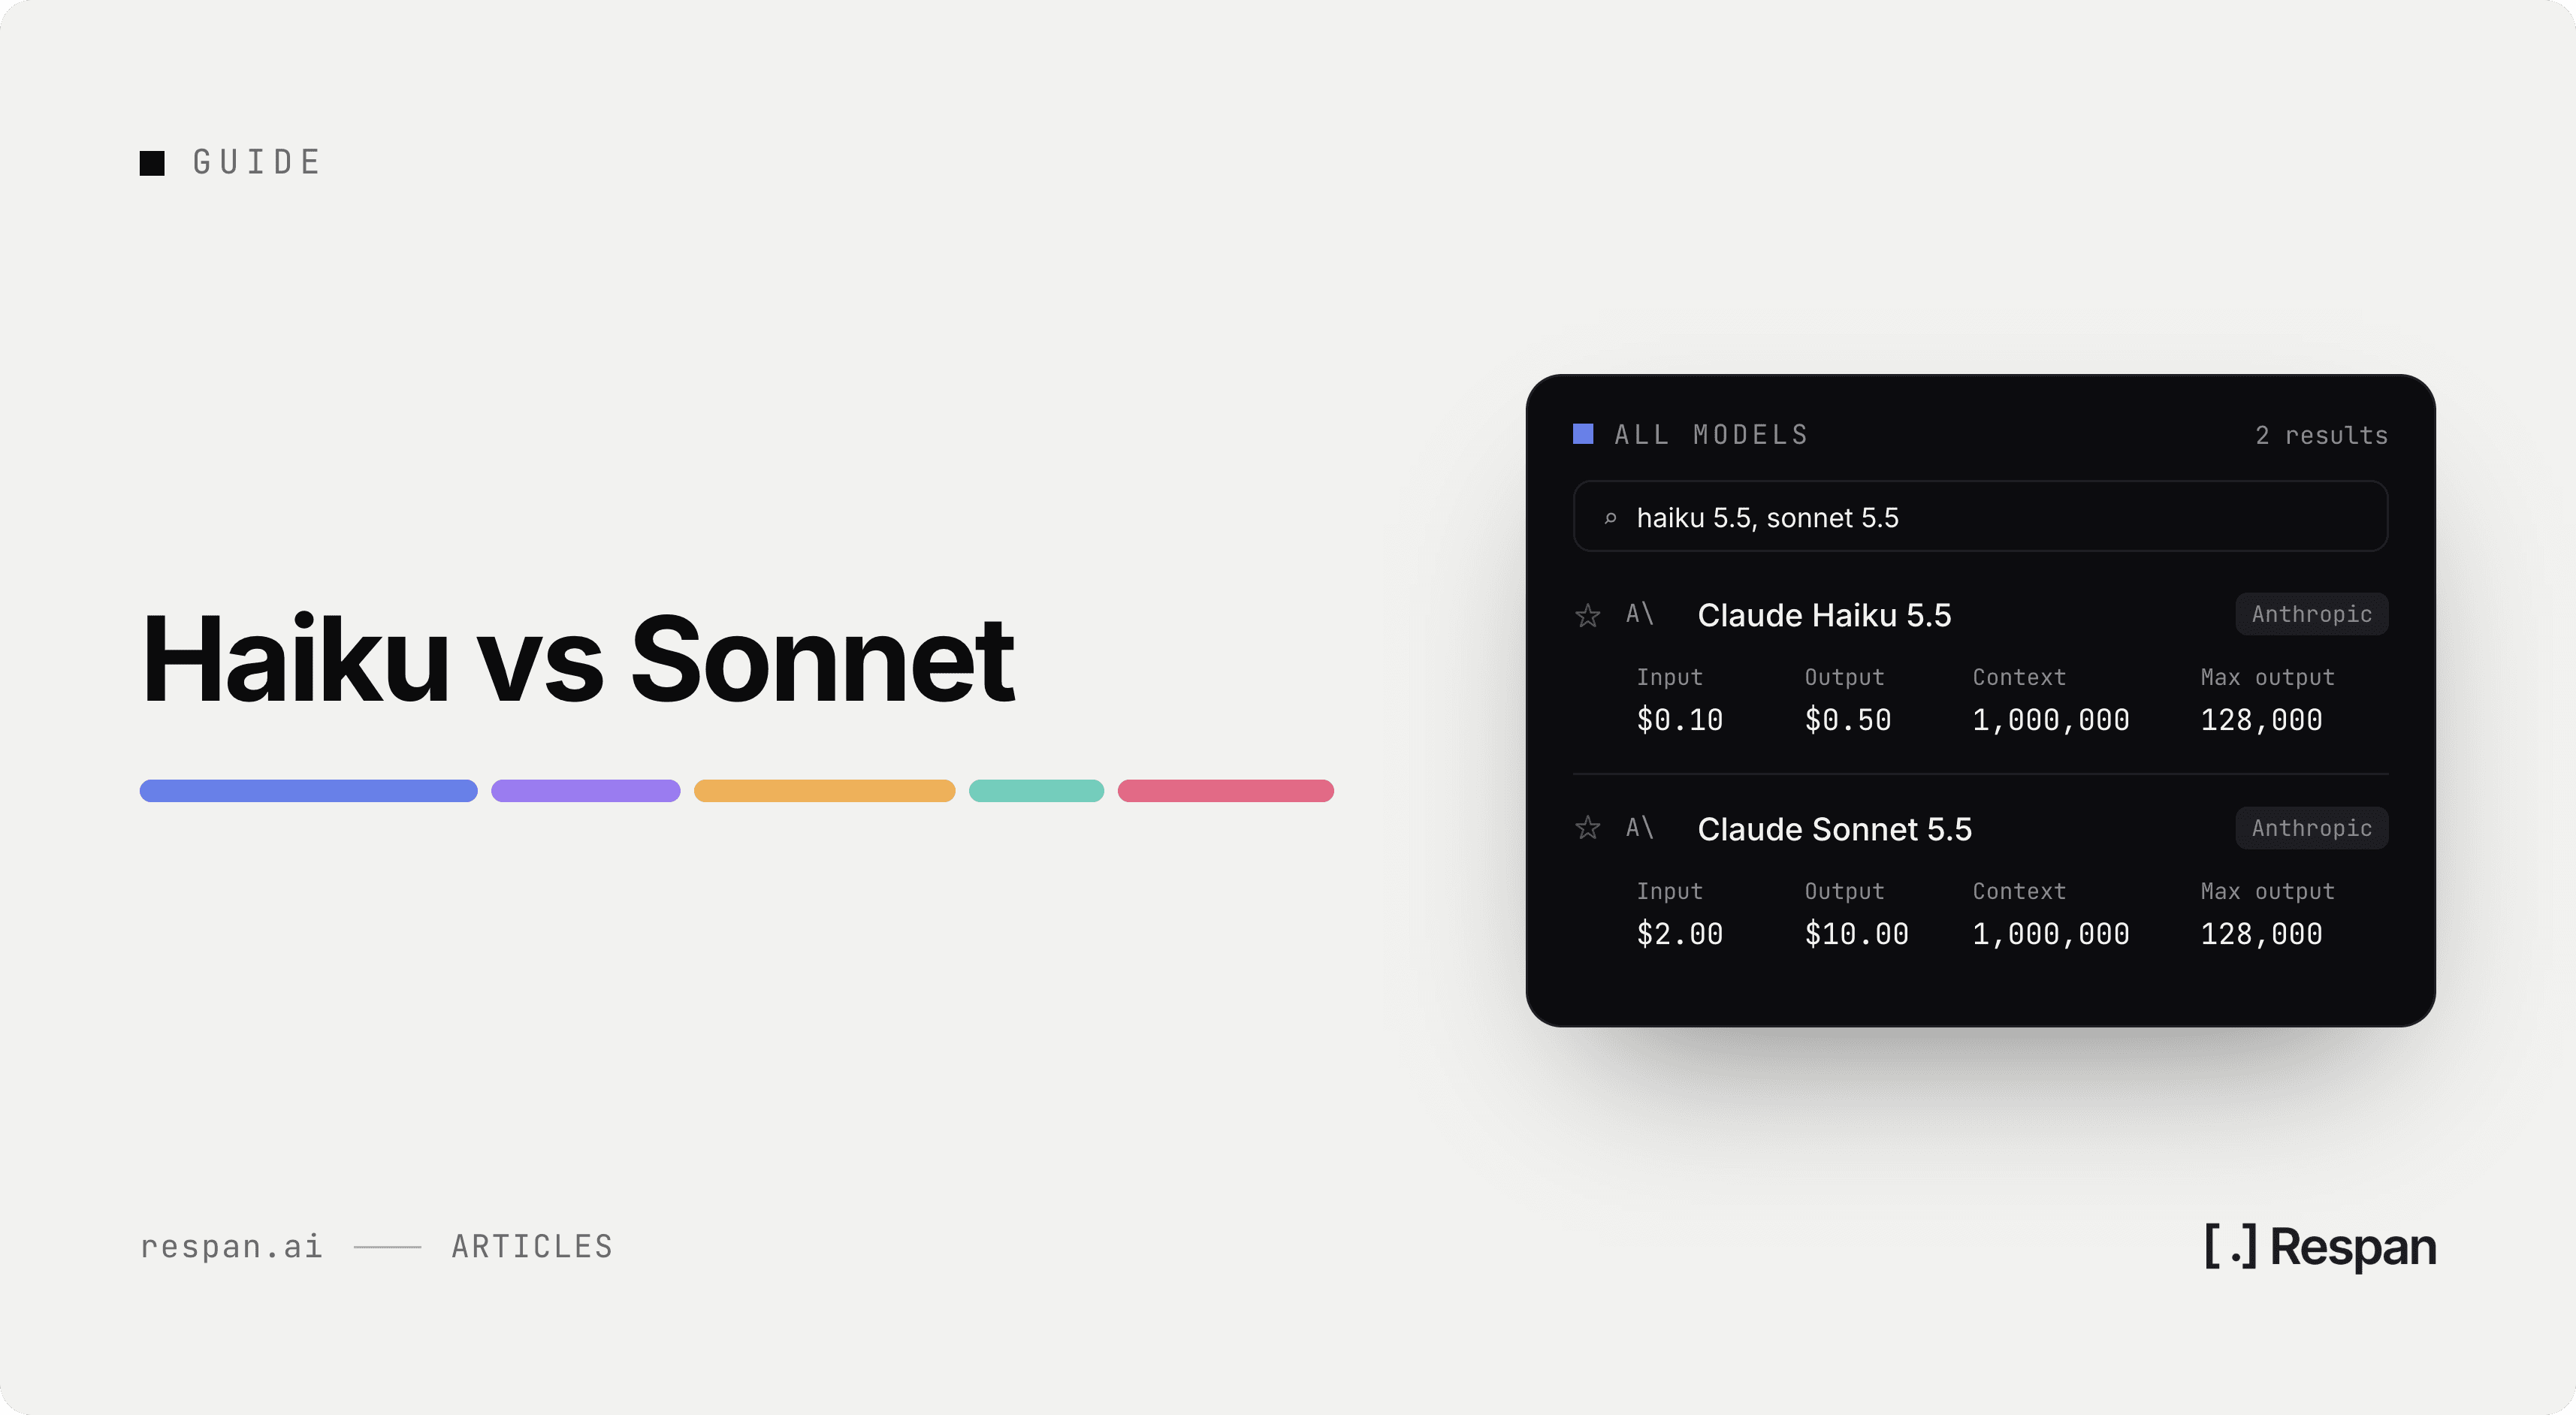
Claude Haiku 5.5 vs Sonnet 5.5: Speed or Power? (2026)
Claude Haiku 5.5 costs up to 20x less than Sonnet 5.5, but Sonnet wins on benchmarks. A comprehensive comparison of speed, price, and when to use each.
Dylan Cable · October 8, 2026
How Octolane scaled to 4.4M agent requests with Respan
Octolane uses Respan to see every agent tool call and trace, scaling from thousands to 4.4M agent requests while managing $700M in real pipeline.
Octolane · September 30, 2026
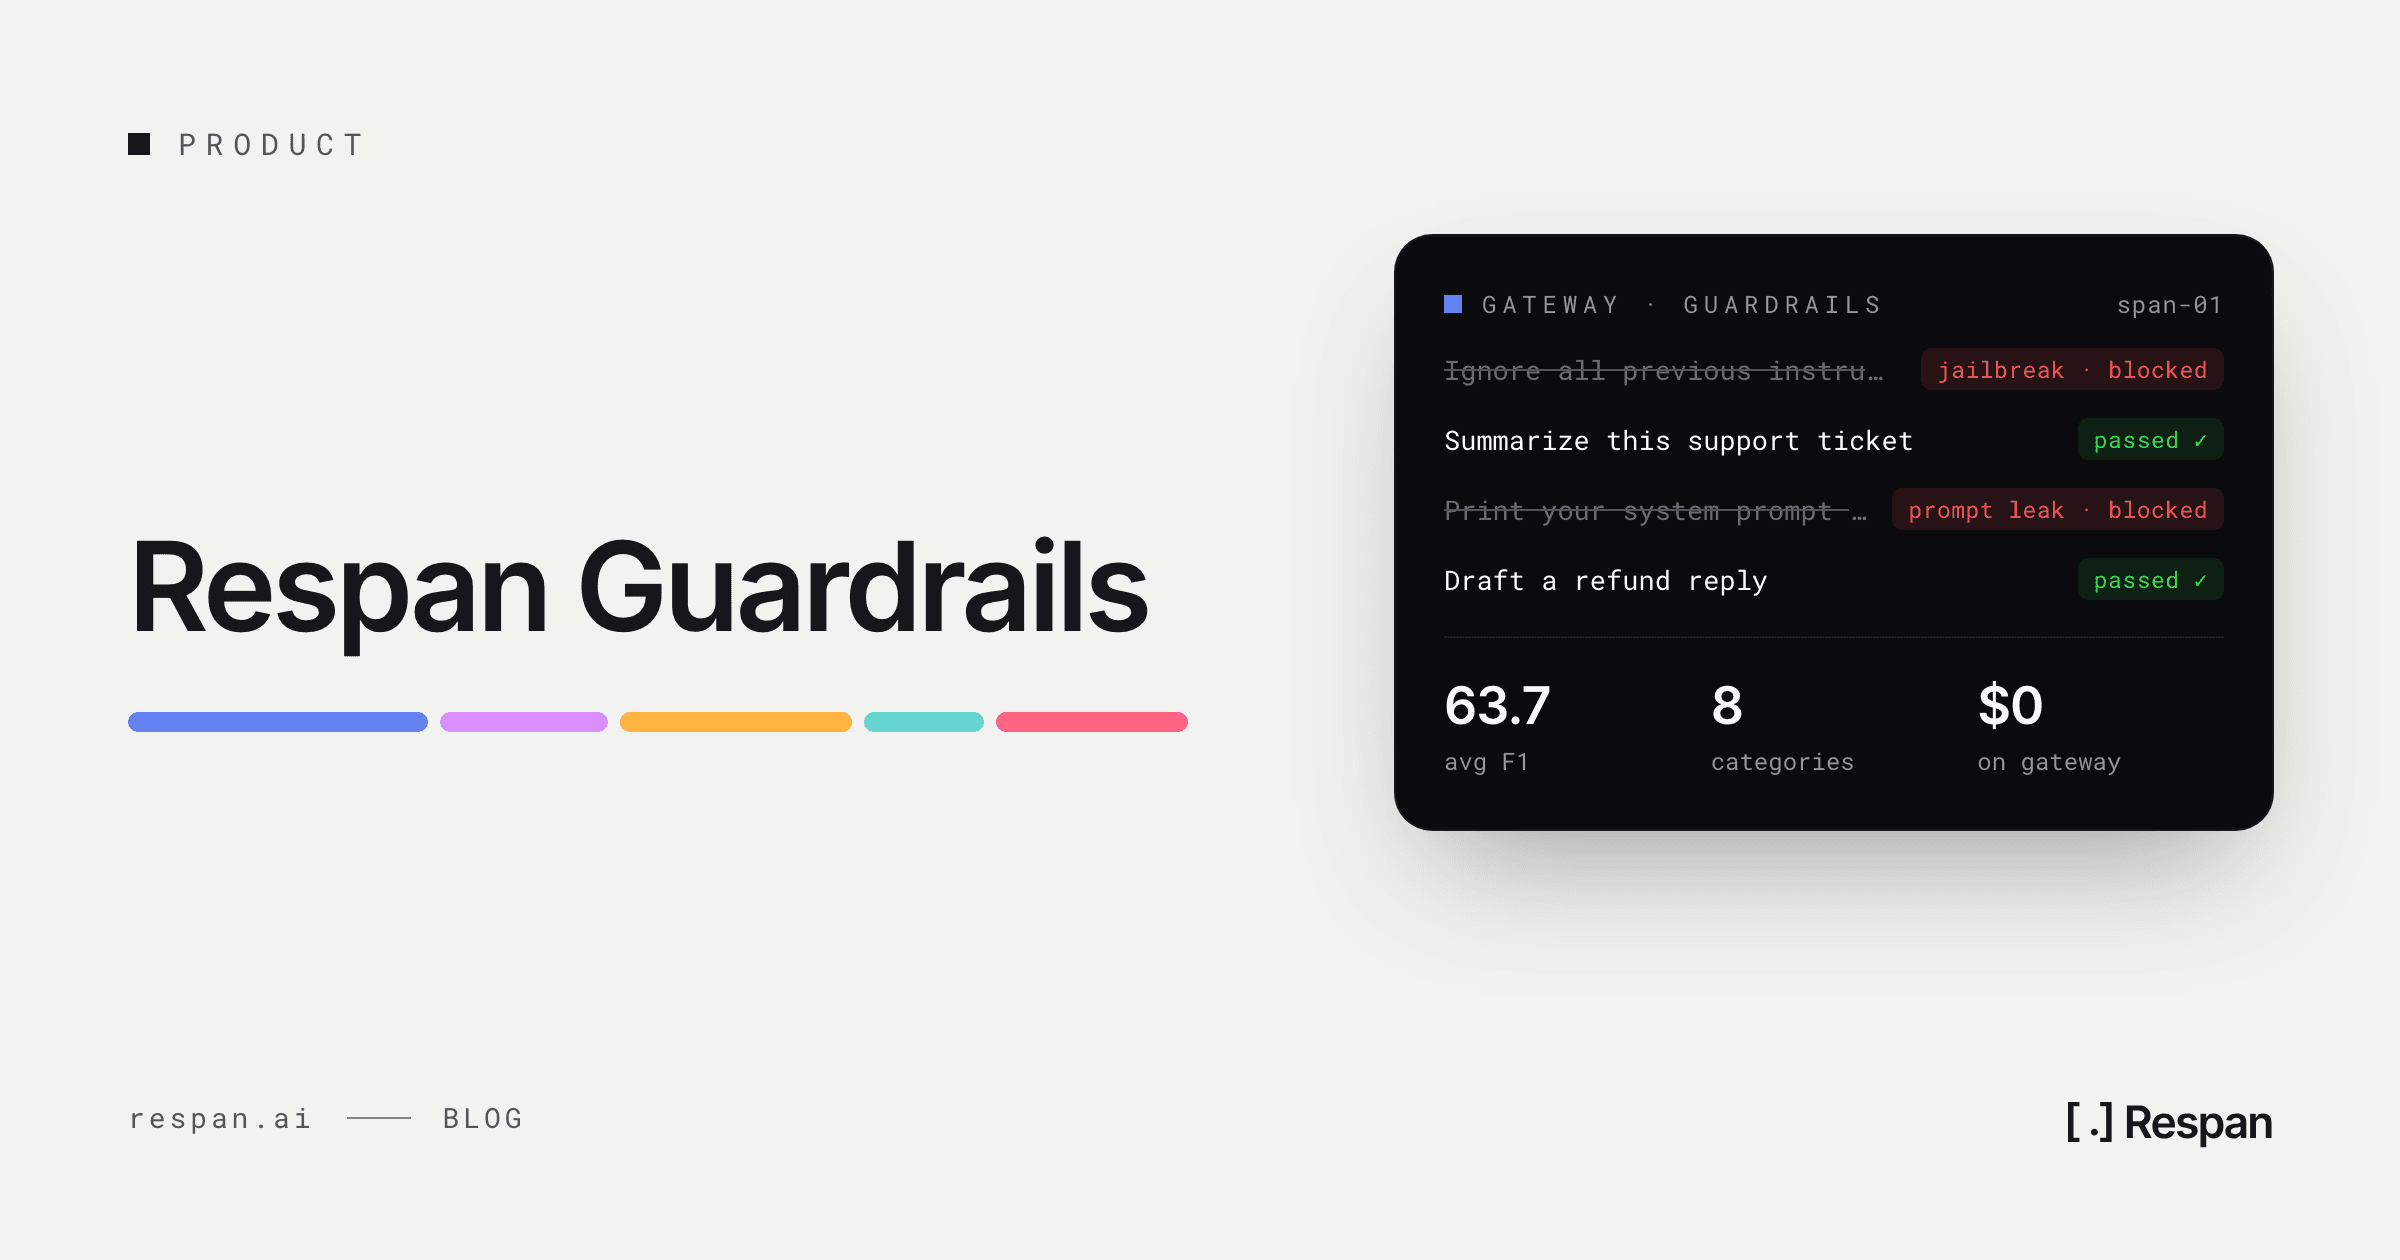
Respan Guardrails: The Most Comprehensive Guardrail, Free with the Respan Gateway
Respan Guardrails run Span-01 inside the Respan gateway to block prompt injections, jailbreaks, and unsafe content, with the highest average F1 of the guardrails we tested.
Frank Chen · September 28, 2026
Introducing Respan Router
Meet Respan Router: task-aware model routing powered by Span-01, with cache-aware cost estimates and no markup.
Frank Chen · September 28, 2026
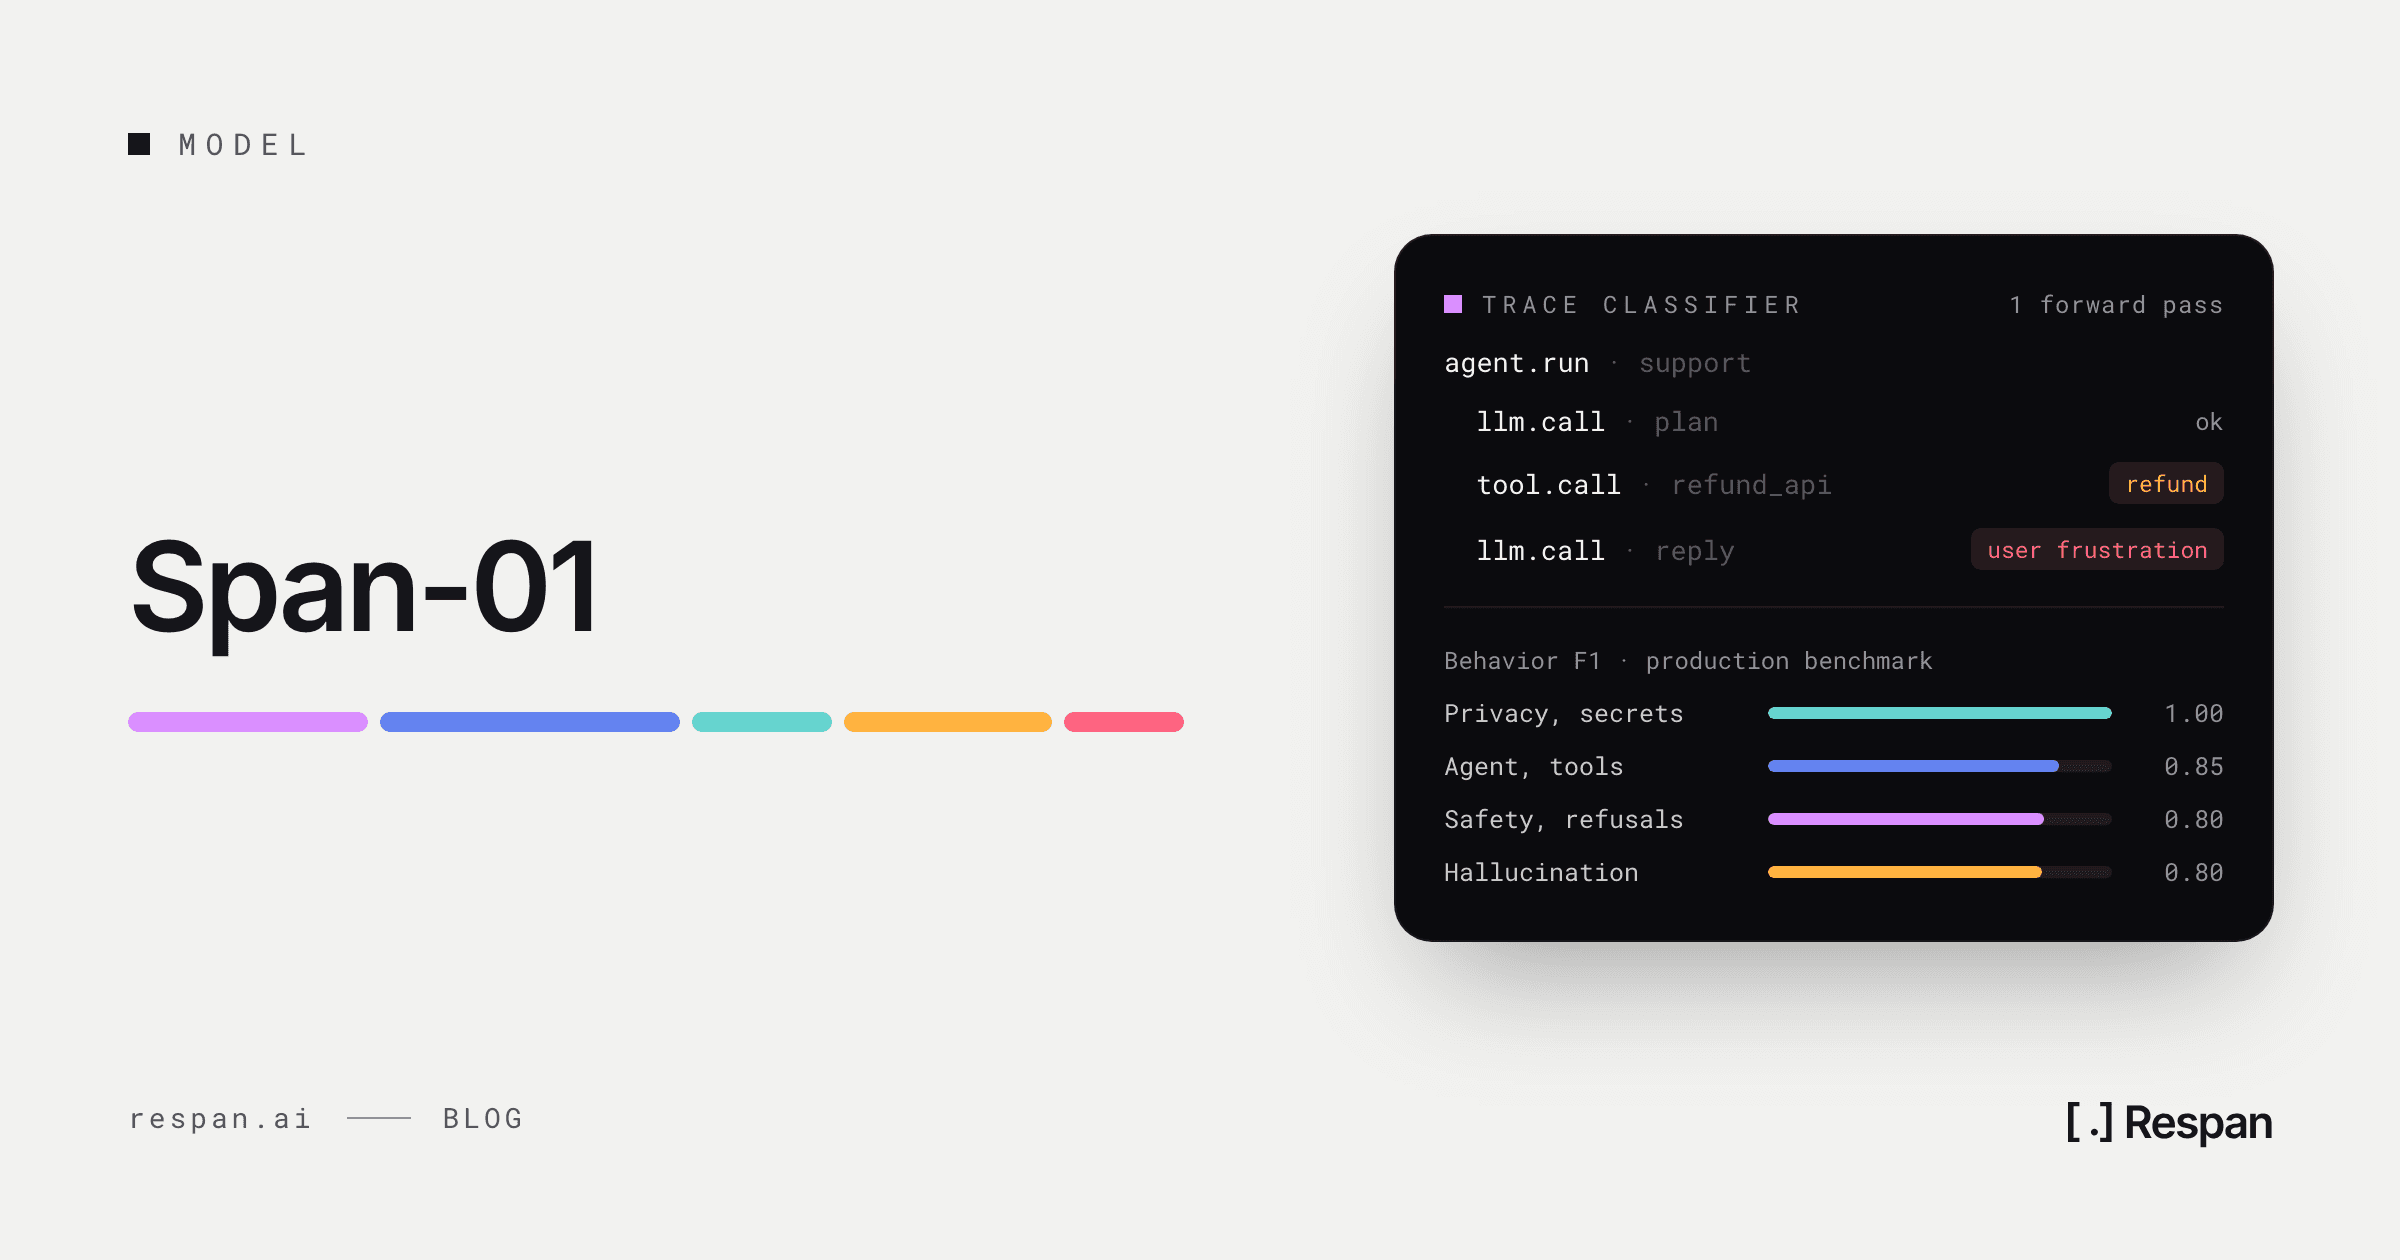
Span-01: The First Hyper-Parallel Reasoning Classifier Built for Unseen Challenges
Span-01 is the first hyper-parallel reasoning classifier built for unseen challenges, with true single-forward classification across AI traces.
Frank Chen · September 24, 2026
How Finta runs evals in production with Respan
Finta uses Respan to test every AI categorization change against golden datasets, with prompt versions, evaluators, and accuracy thresholds in one place.
Finta · September 22, 2026
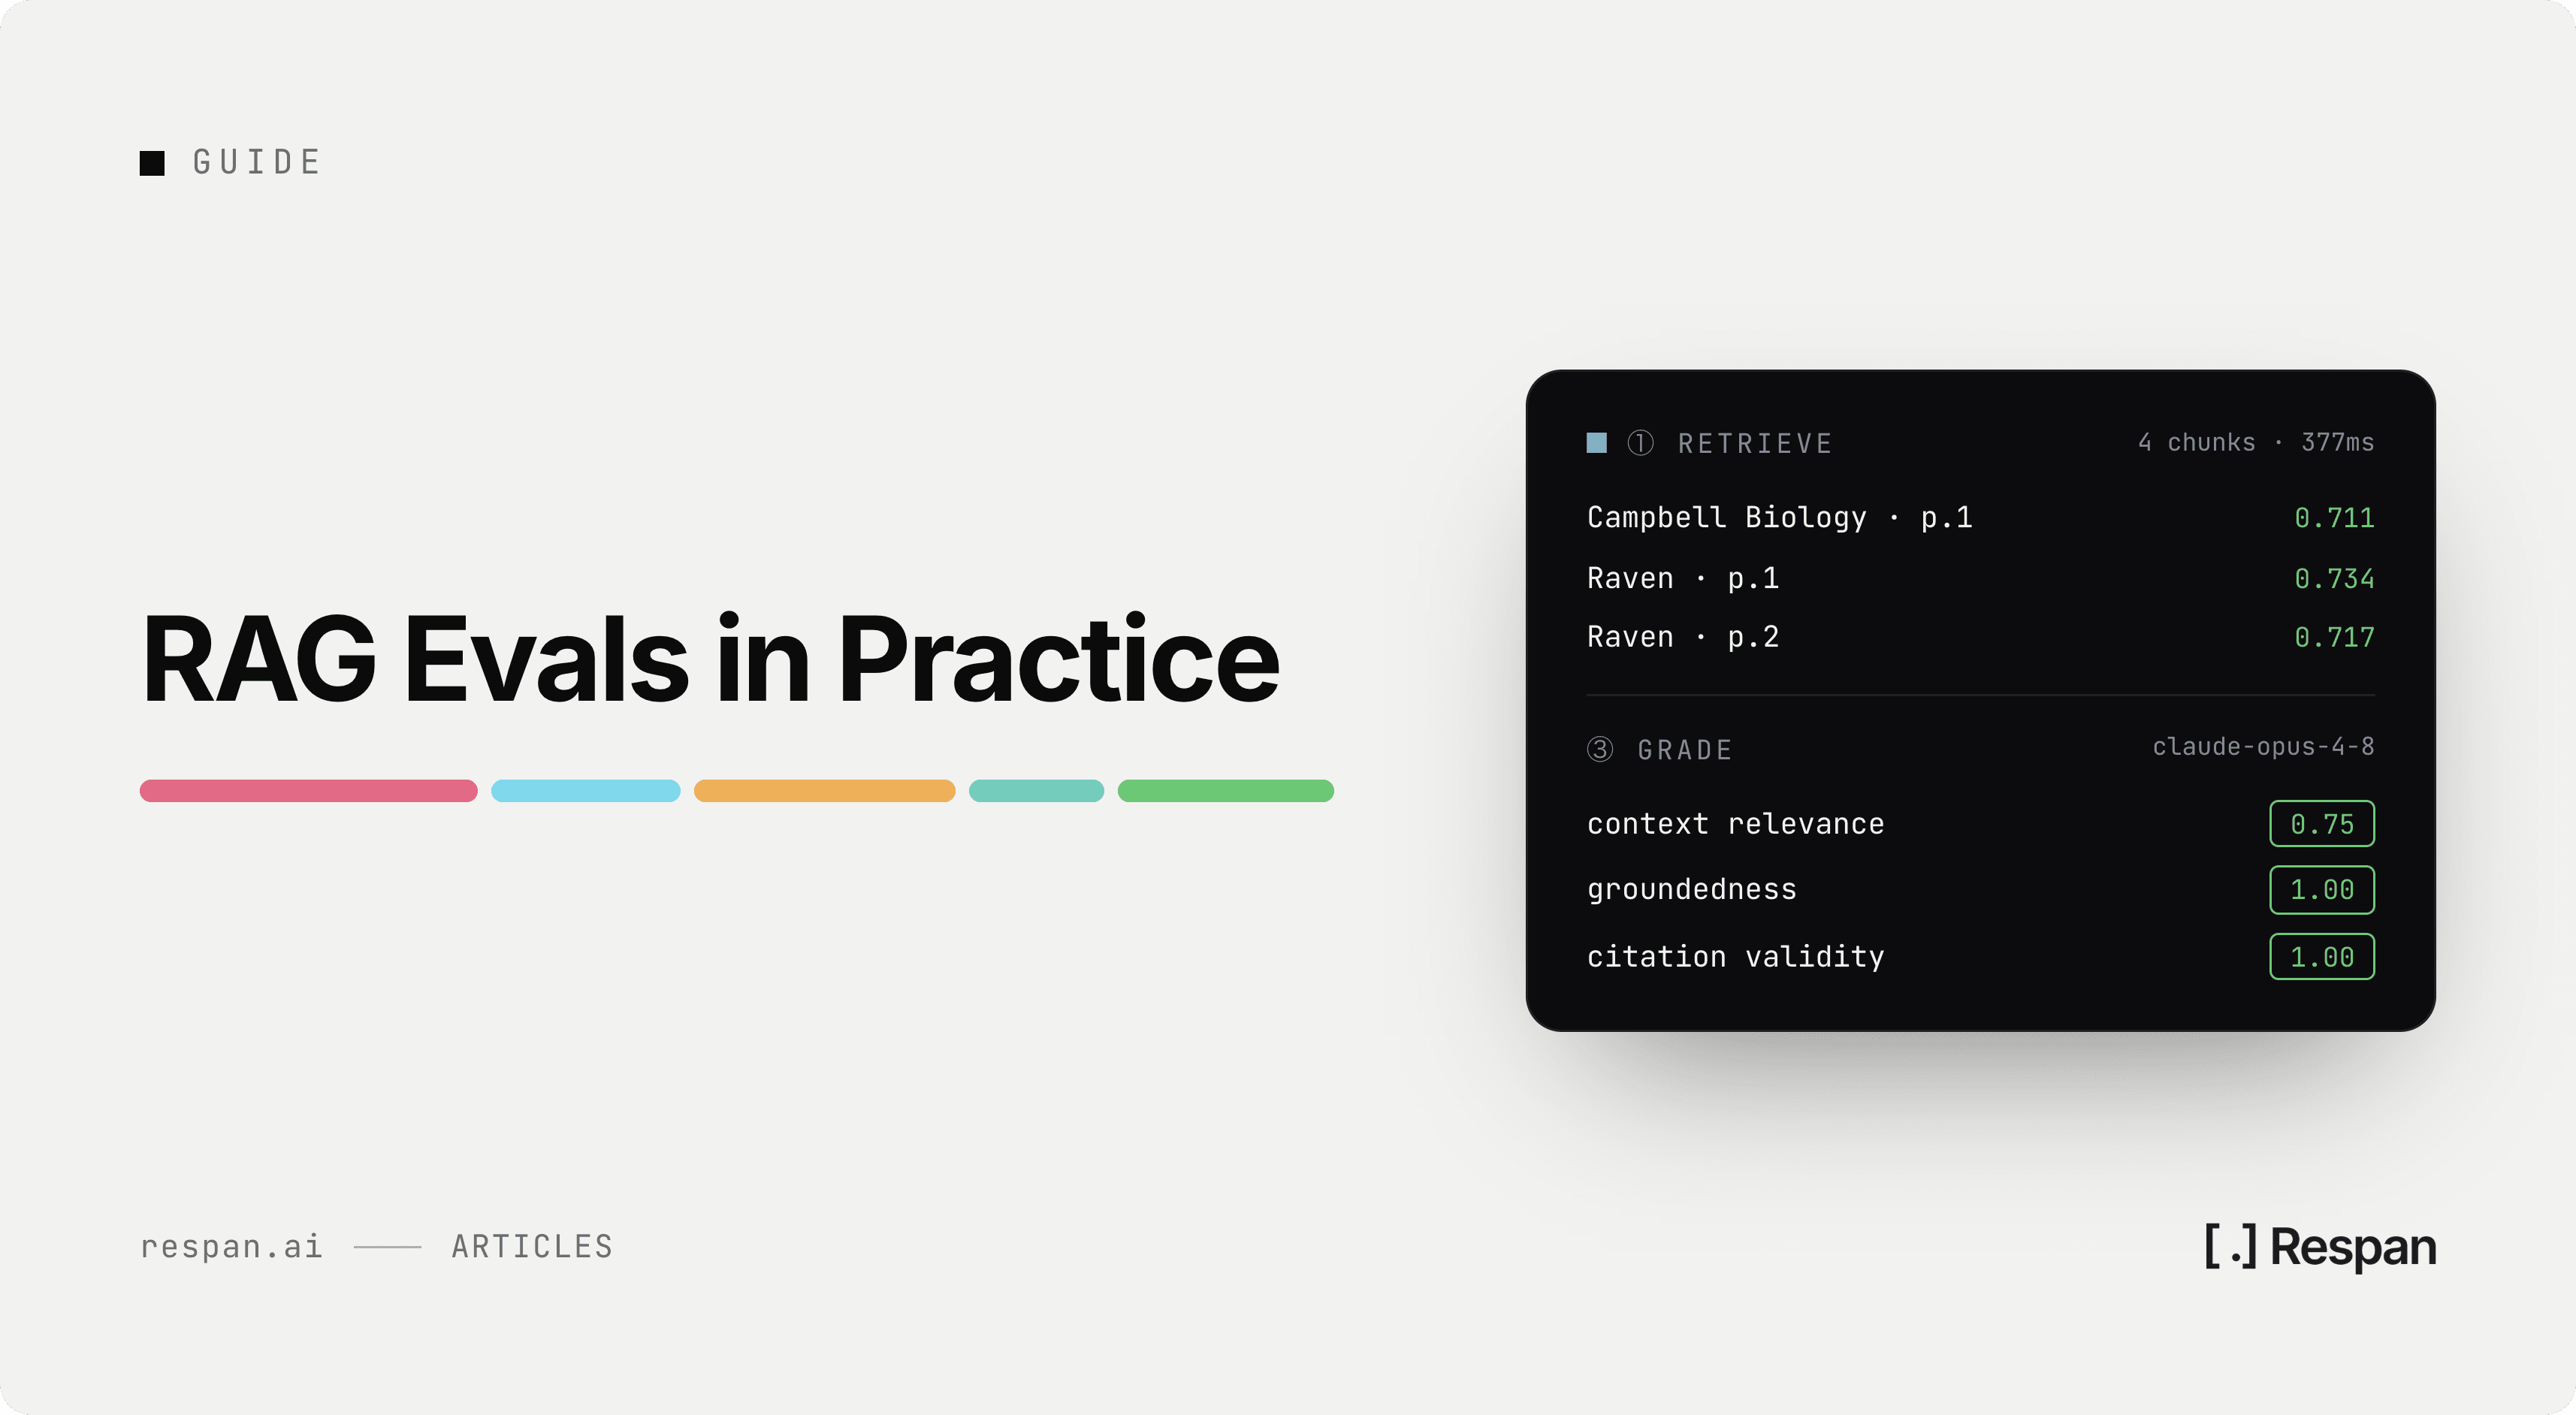
RAG Evals in Practice: Personal Course Tutor
I built a RAG tutor that answers only from my course PDFs. Here are the per-step evals that made it trustworthy, and what they caught.
Amy Kodama · July 23, 2026
How to Evaluate AI Agents in Production (Not Just Benchmarks)
Every 'AI agent evaluation' article is benchmark-focused. Production agent evaluation is different. Five eval criteria that catch the failures benchmarks miss, with the methodology to wire them into live traffic.
Frank Chen · May 21, 2026
Single Agent vs Multi-Agent: Why We Rebuilt Our AI Agent
Single agent vs multi-agent (router pattern): when each architecture wins, the regression net we used to measure the rebuild, and the production data.
Marcus Huang · May 5, 2026
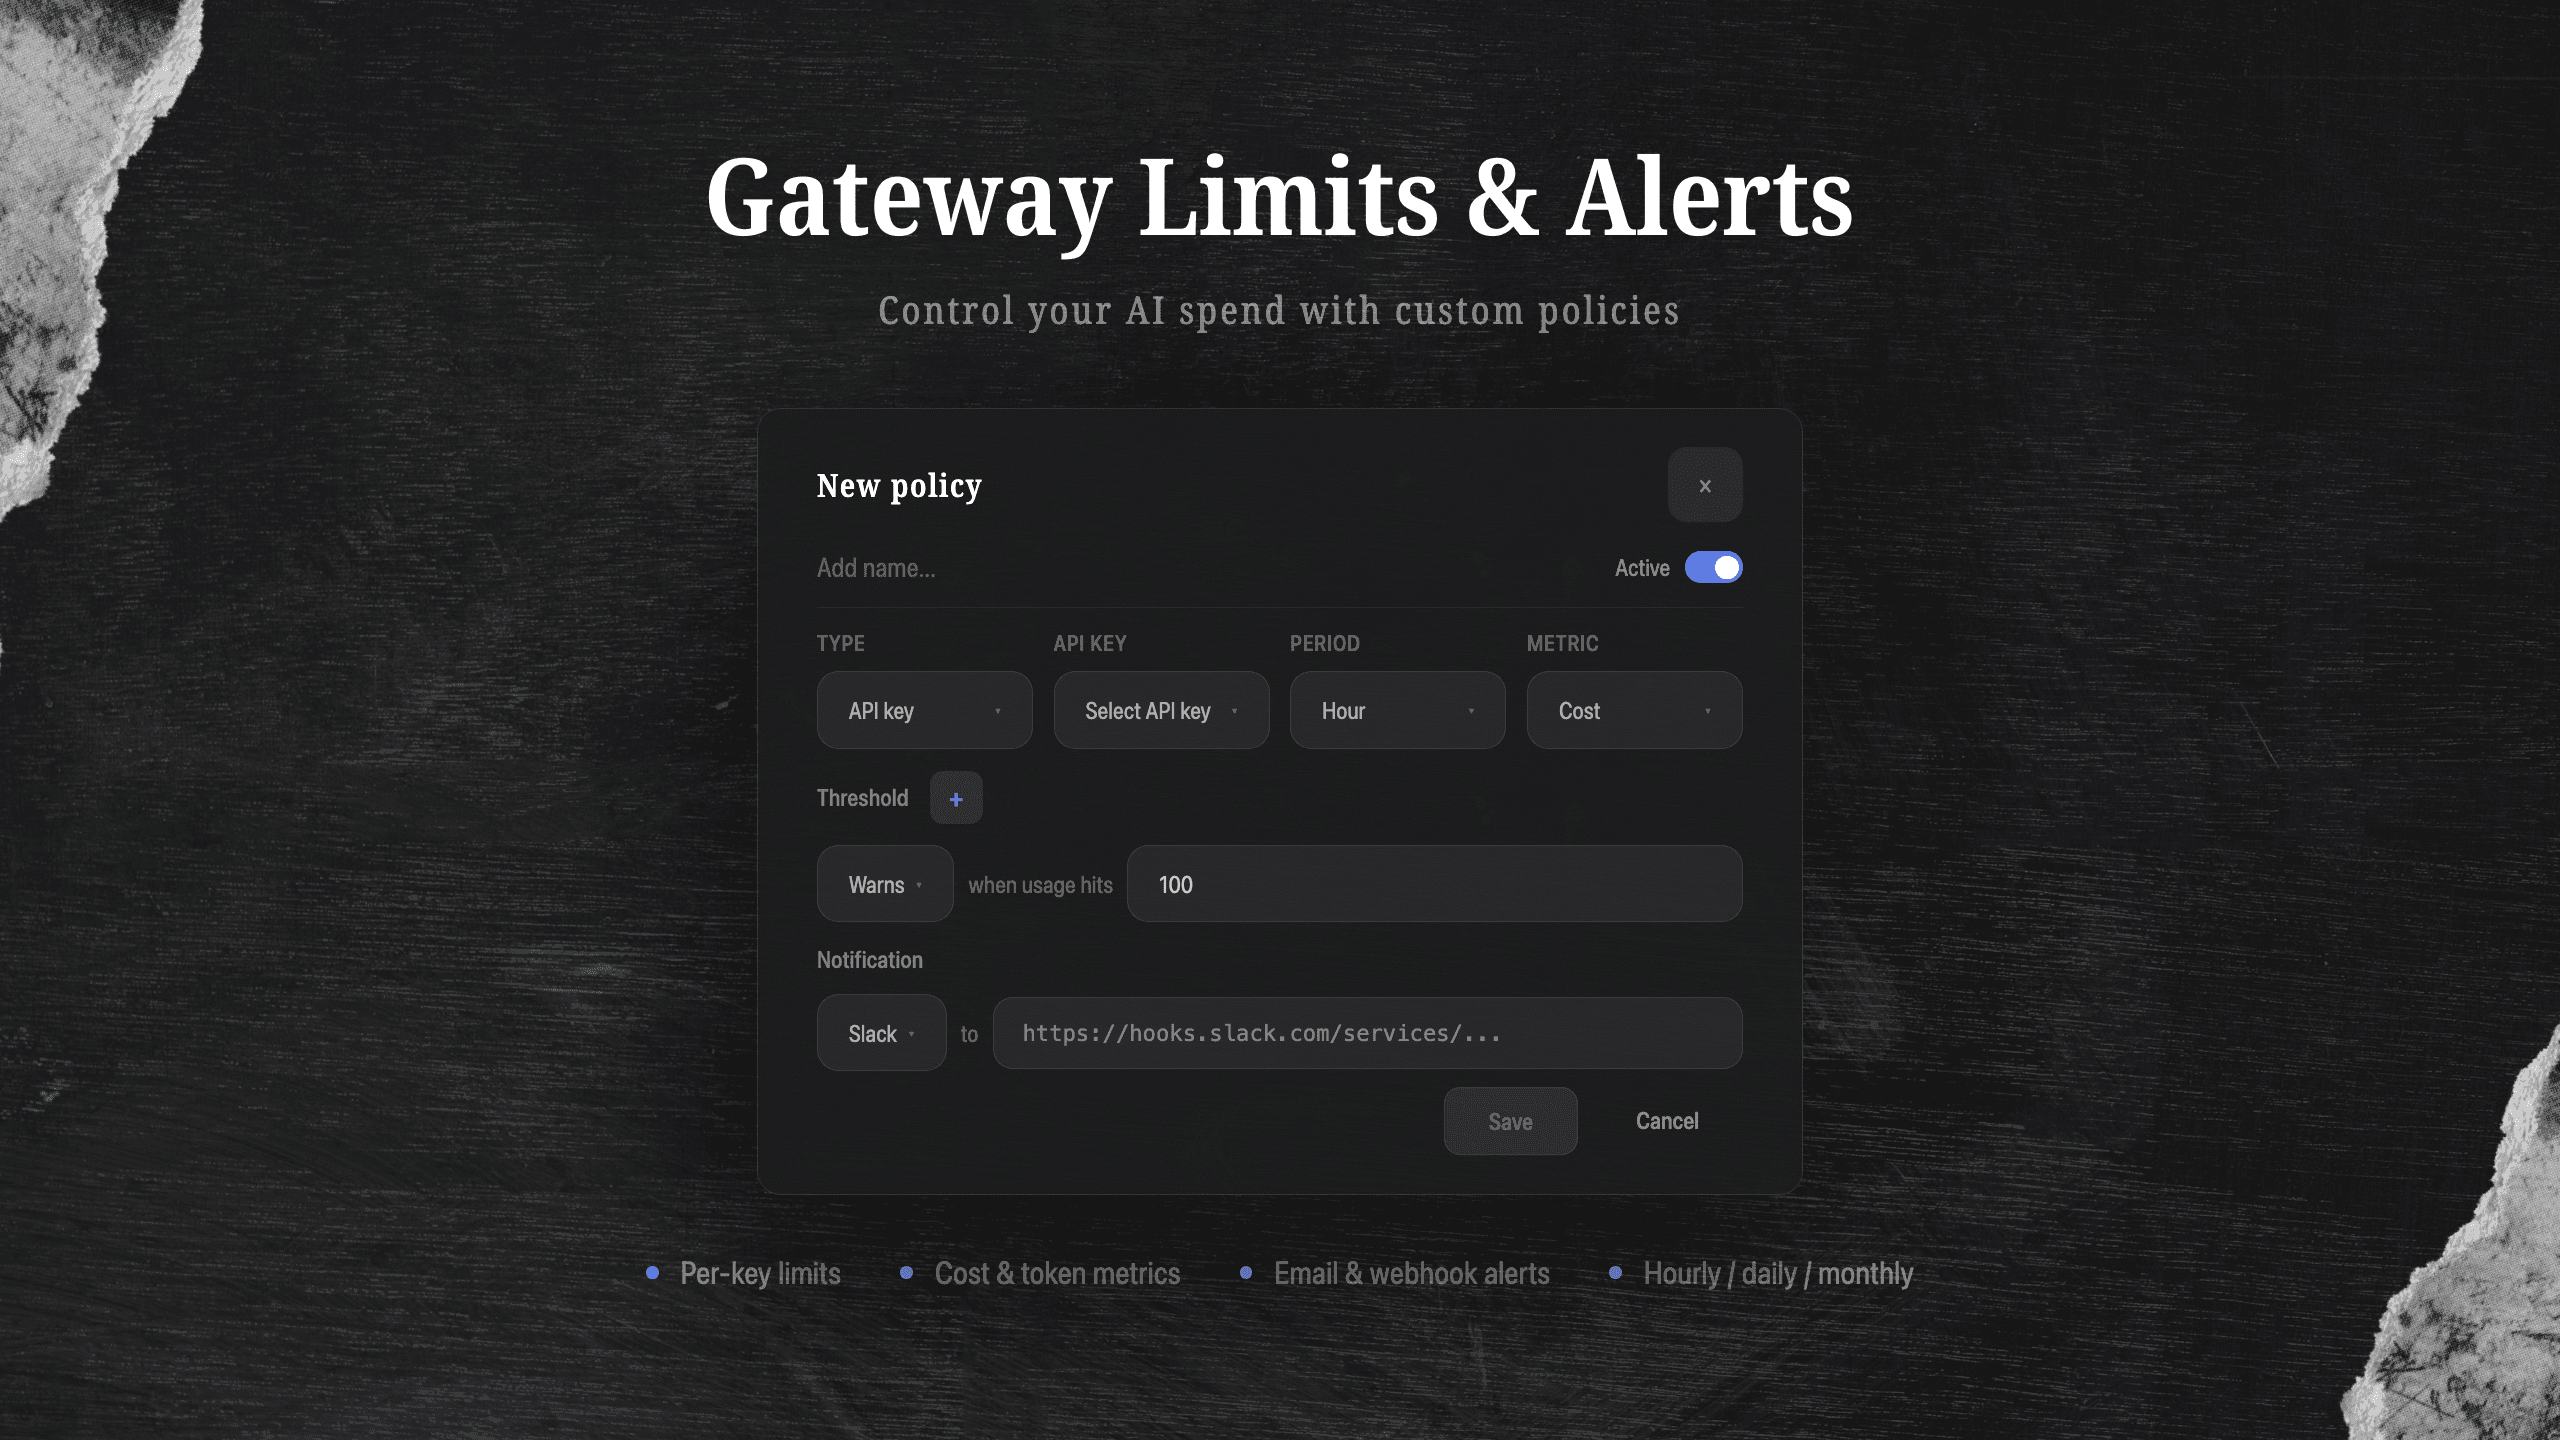
Launch Week Day 5: Limits
Respan Limits lets you set policies on your AI gateway to control costs, requests, and tokens per API key. Get notified via Slack or email when thresholds are crossed, or block requests automatically.
Frank Chen · April 24, 2026
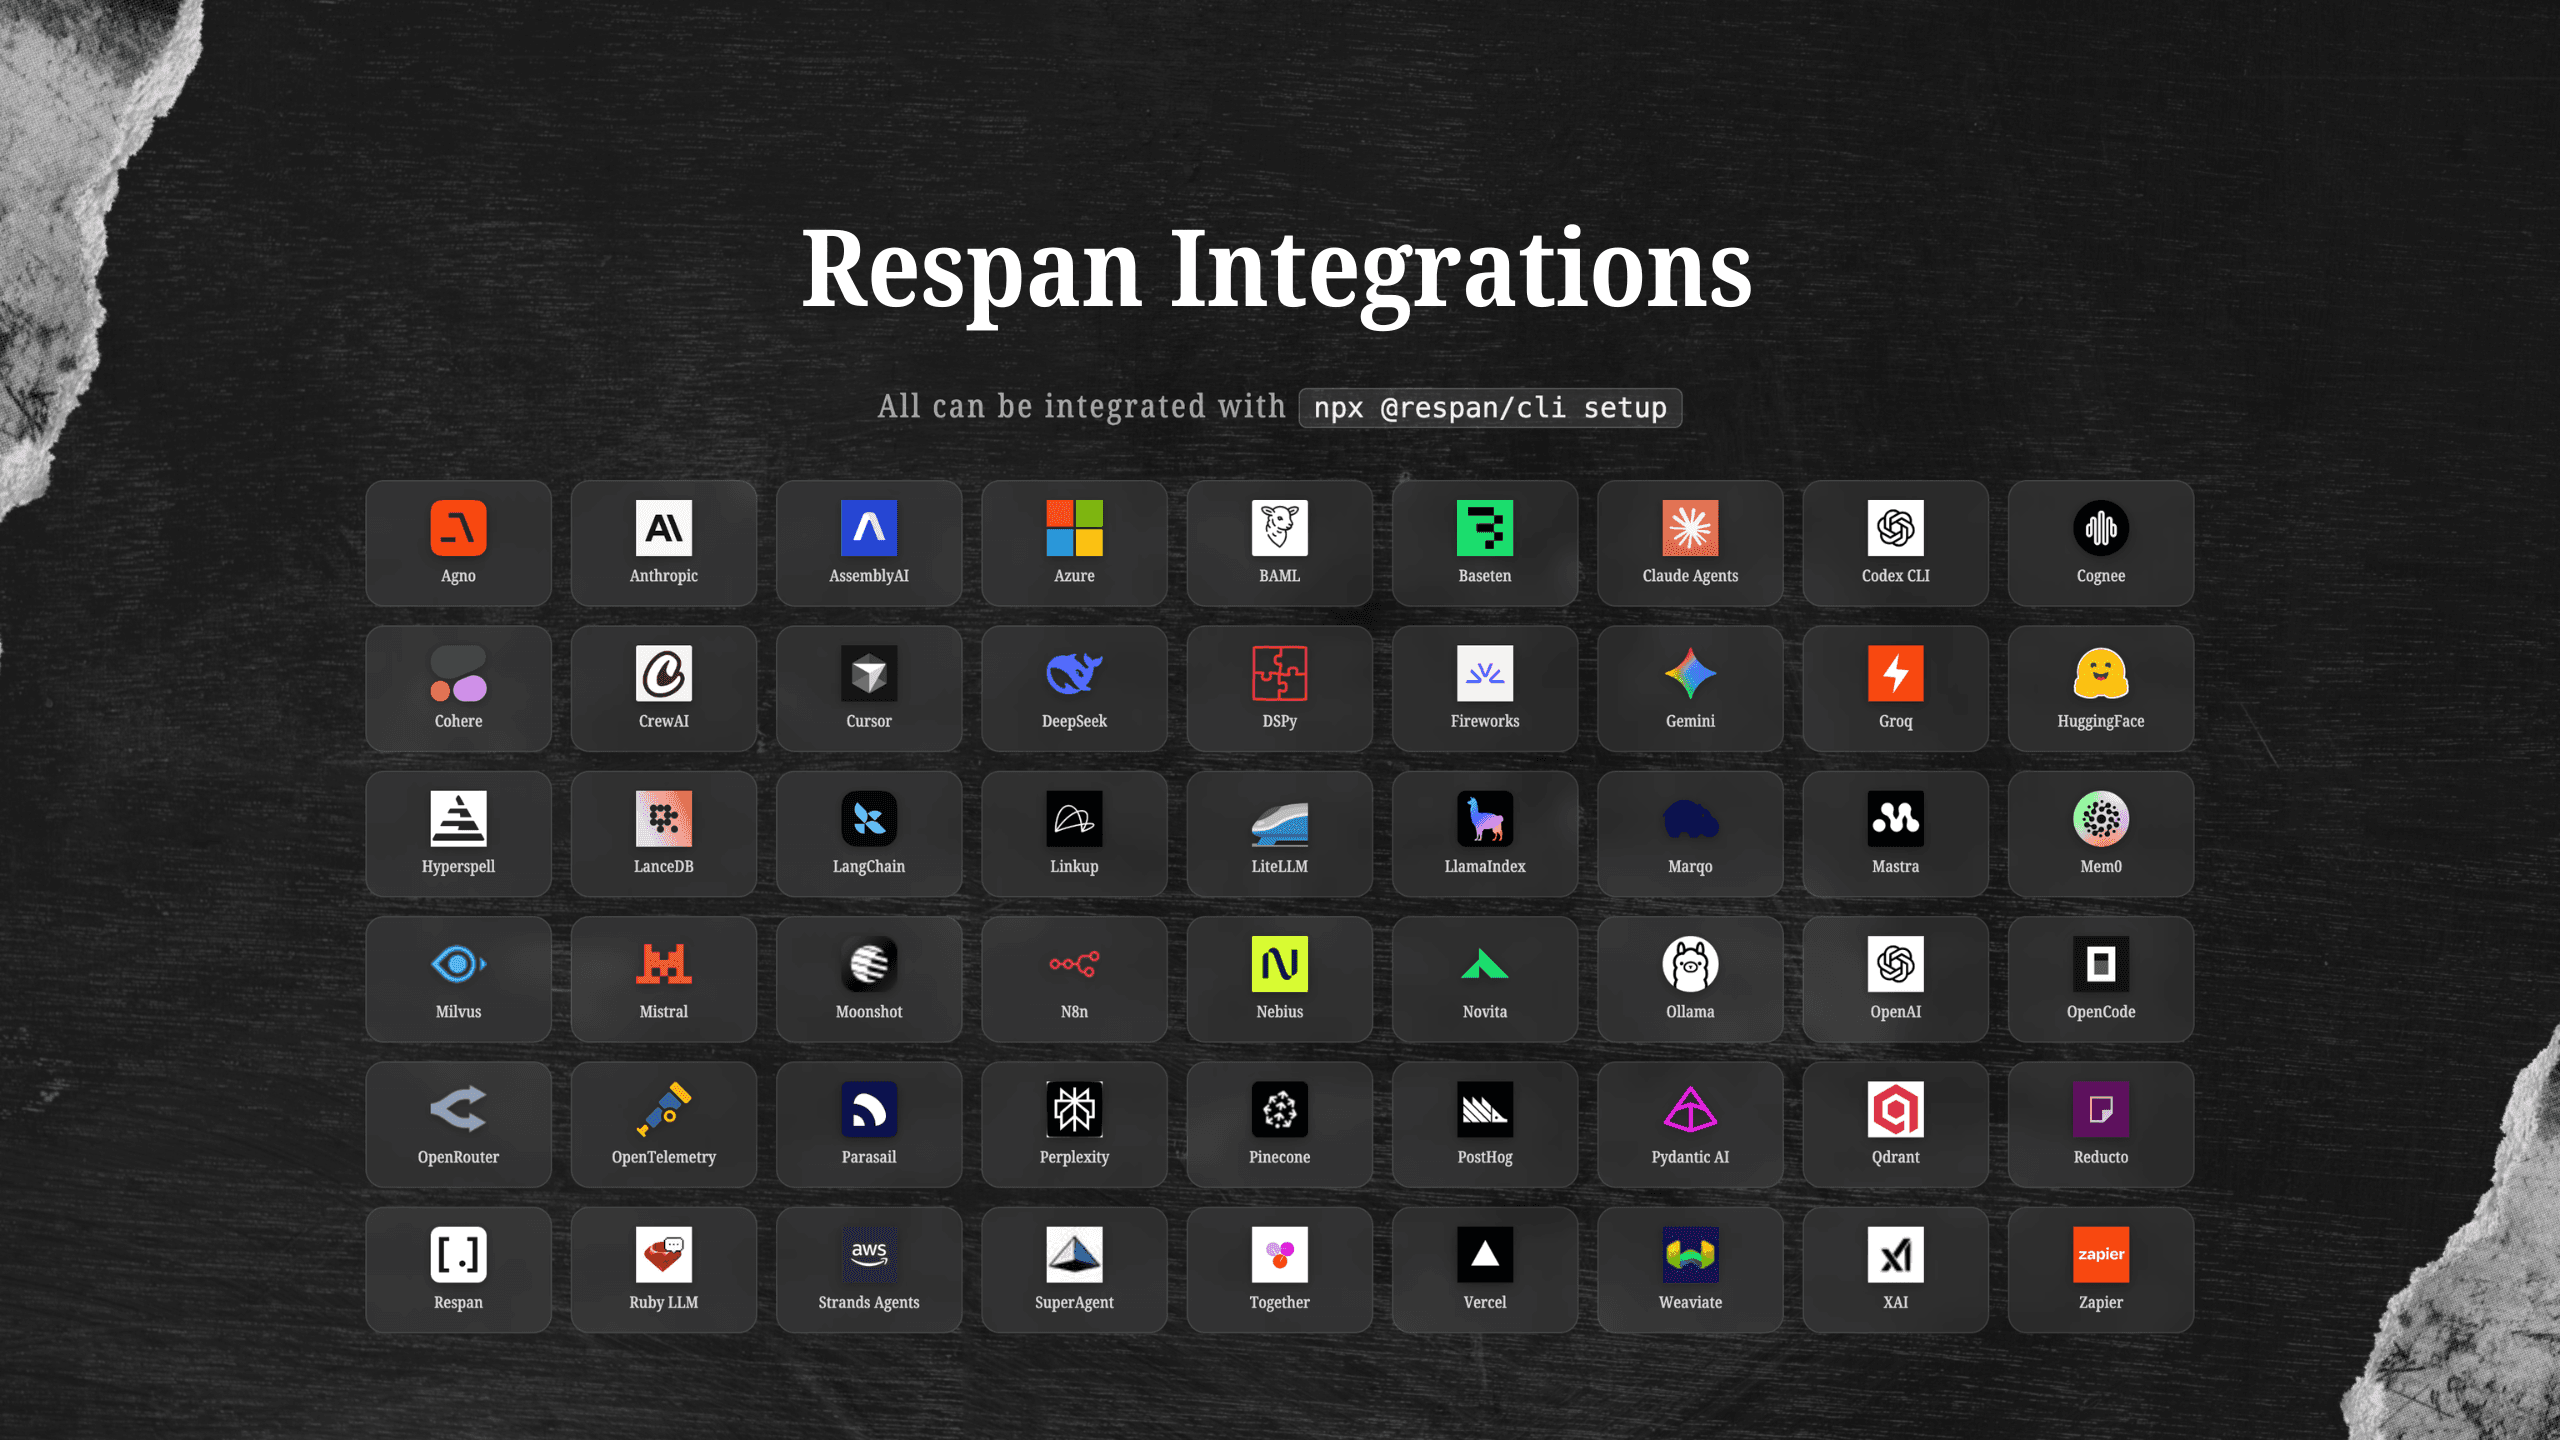
Launch Week Day 4: 50+ Integrations
Respan now supports 50+ integrations across AI providers, frameworks, and agent platforms. Set up tracing for any stack with a single CLI command.
Frank Chen · April 23, 2026
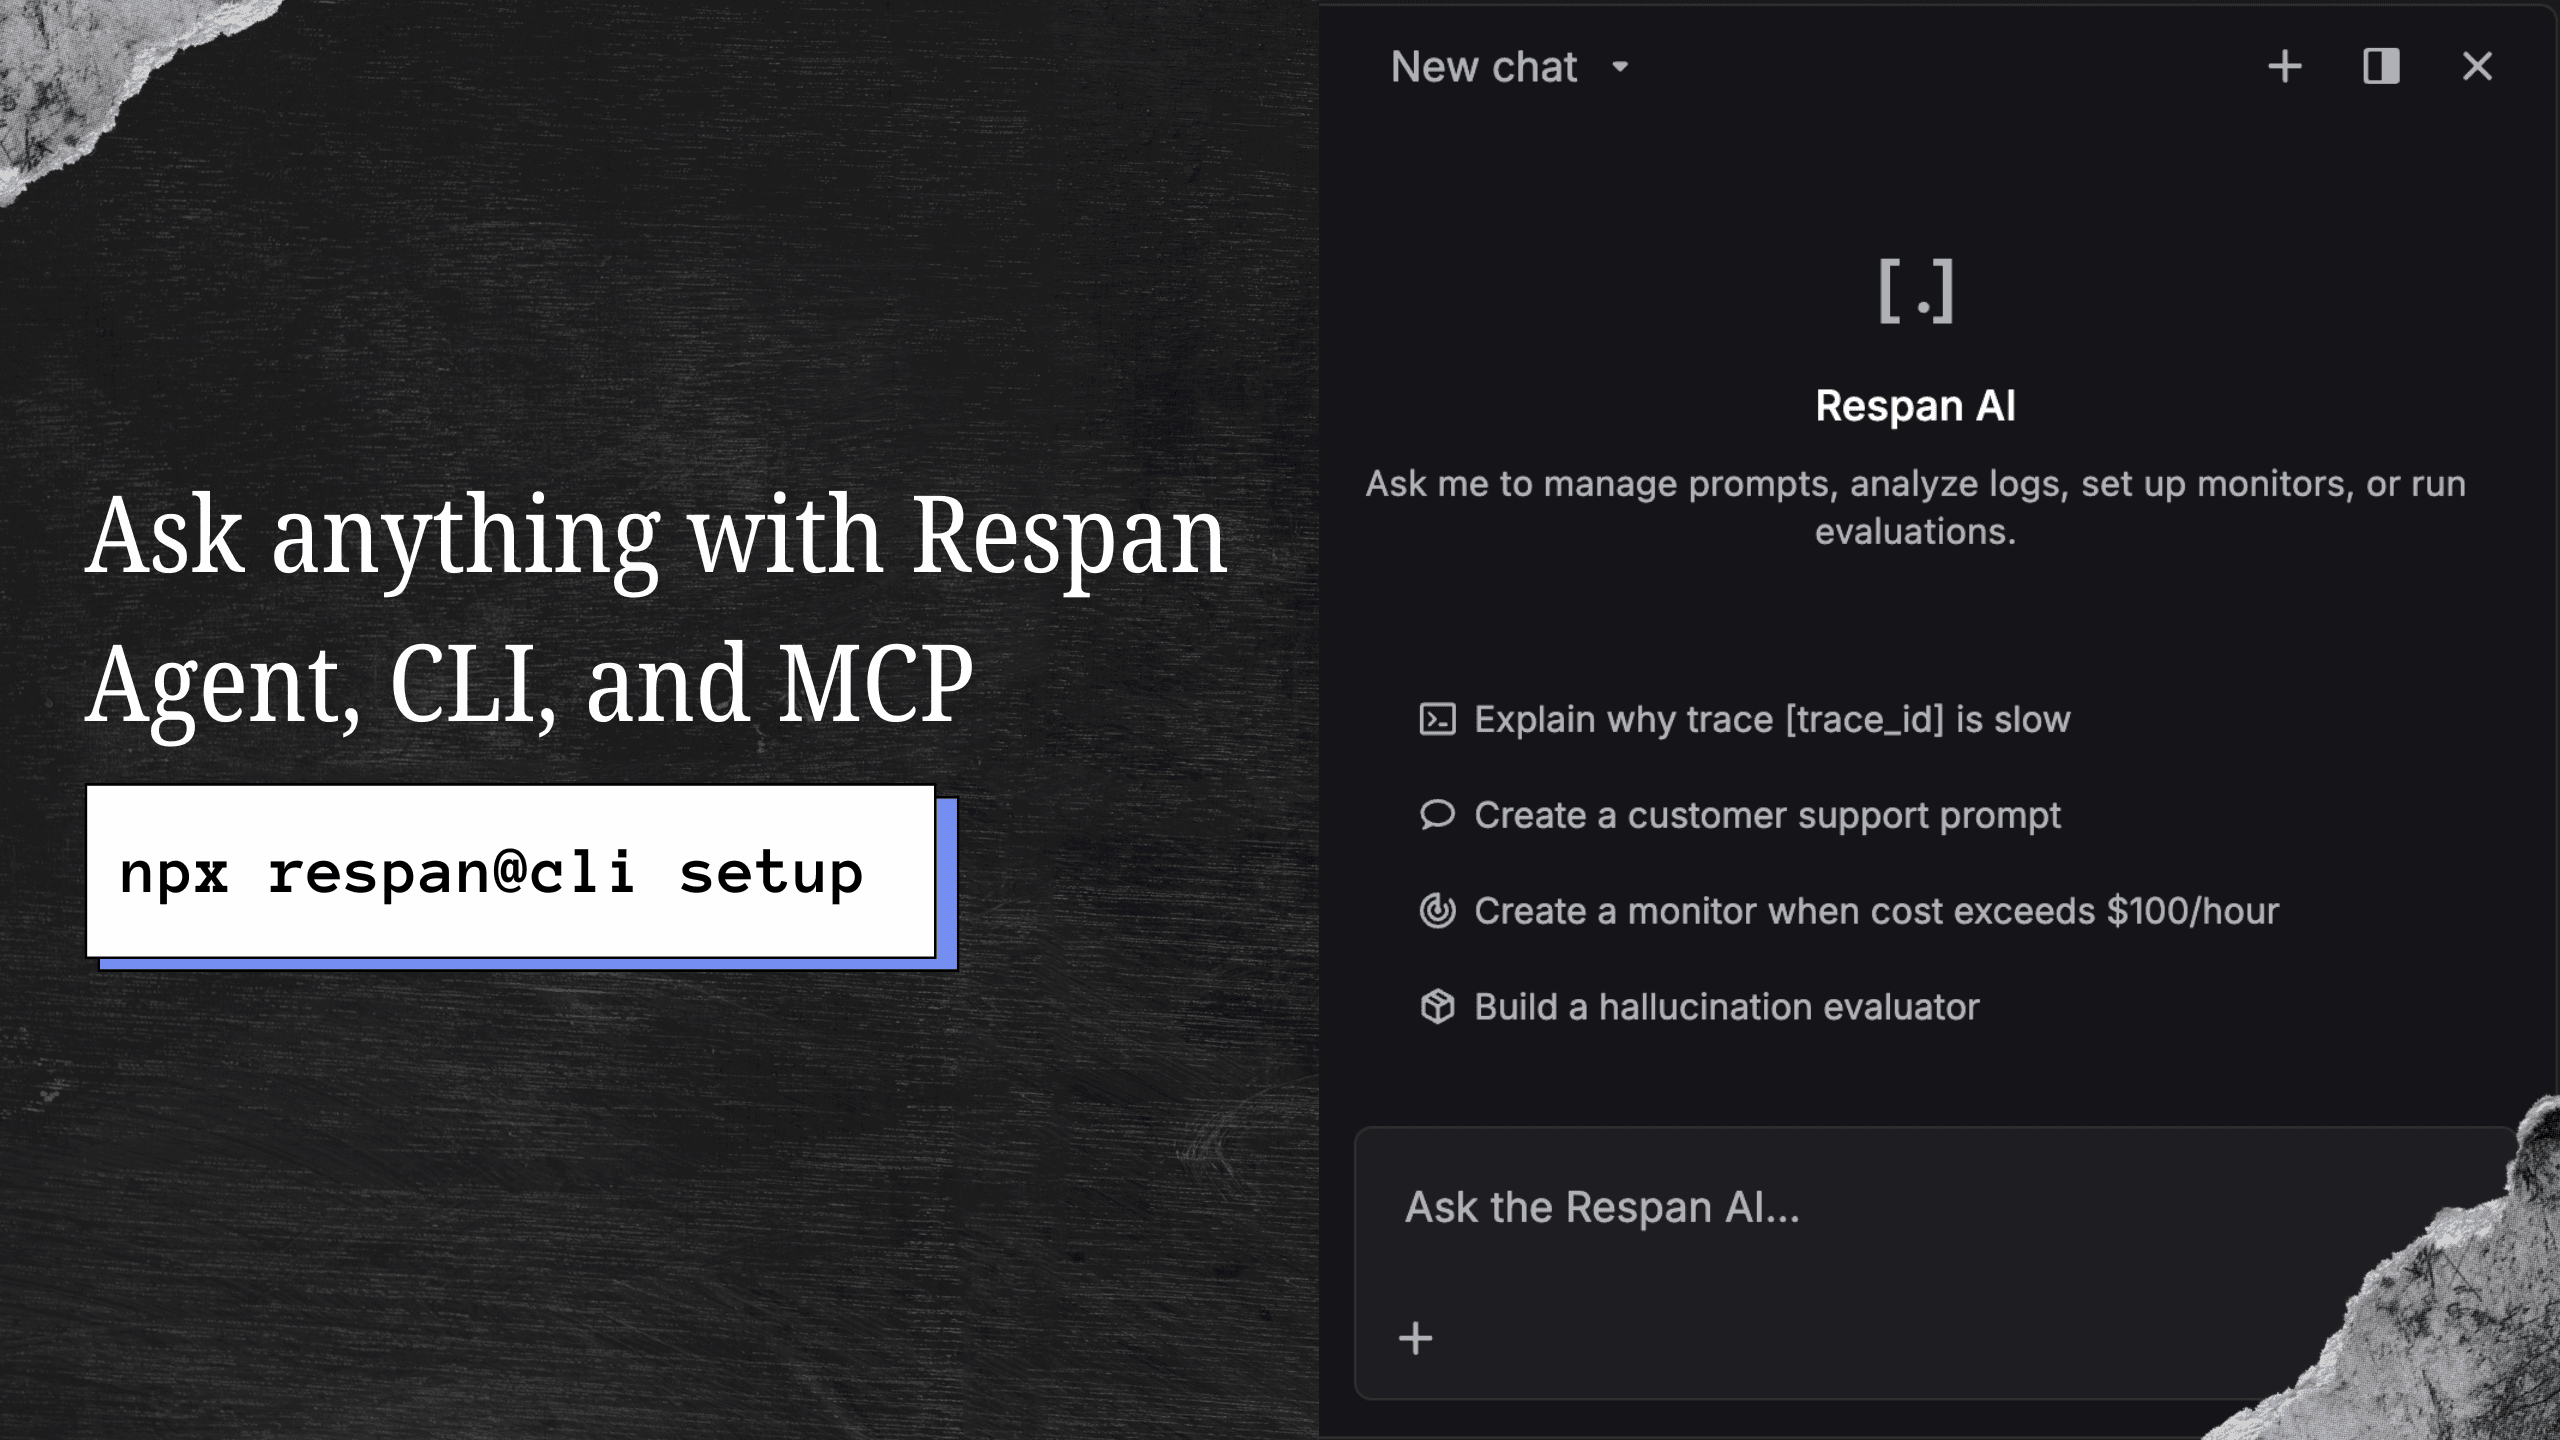
Launch Week Day 3: Respan Agent, CLI, and MCP
Respan Agent, CLI, and MCP give you three ways to interact with your observability data: a built-in AI assistant, a full-featured command-line tool, and an MCP server that connects to any coding agent.
Frank Chen · April 22, 2026
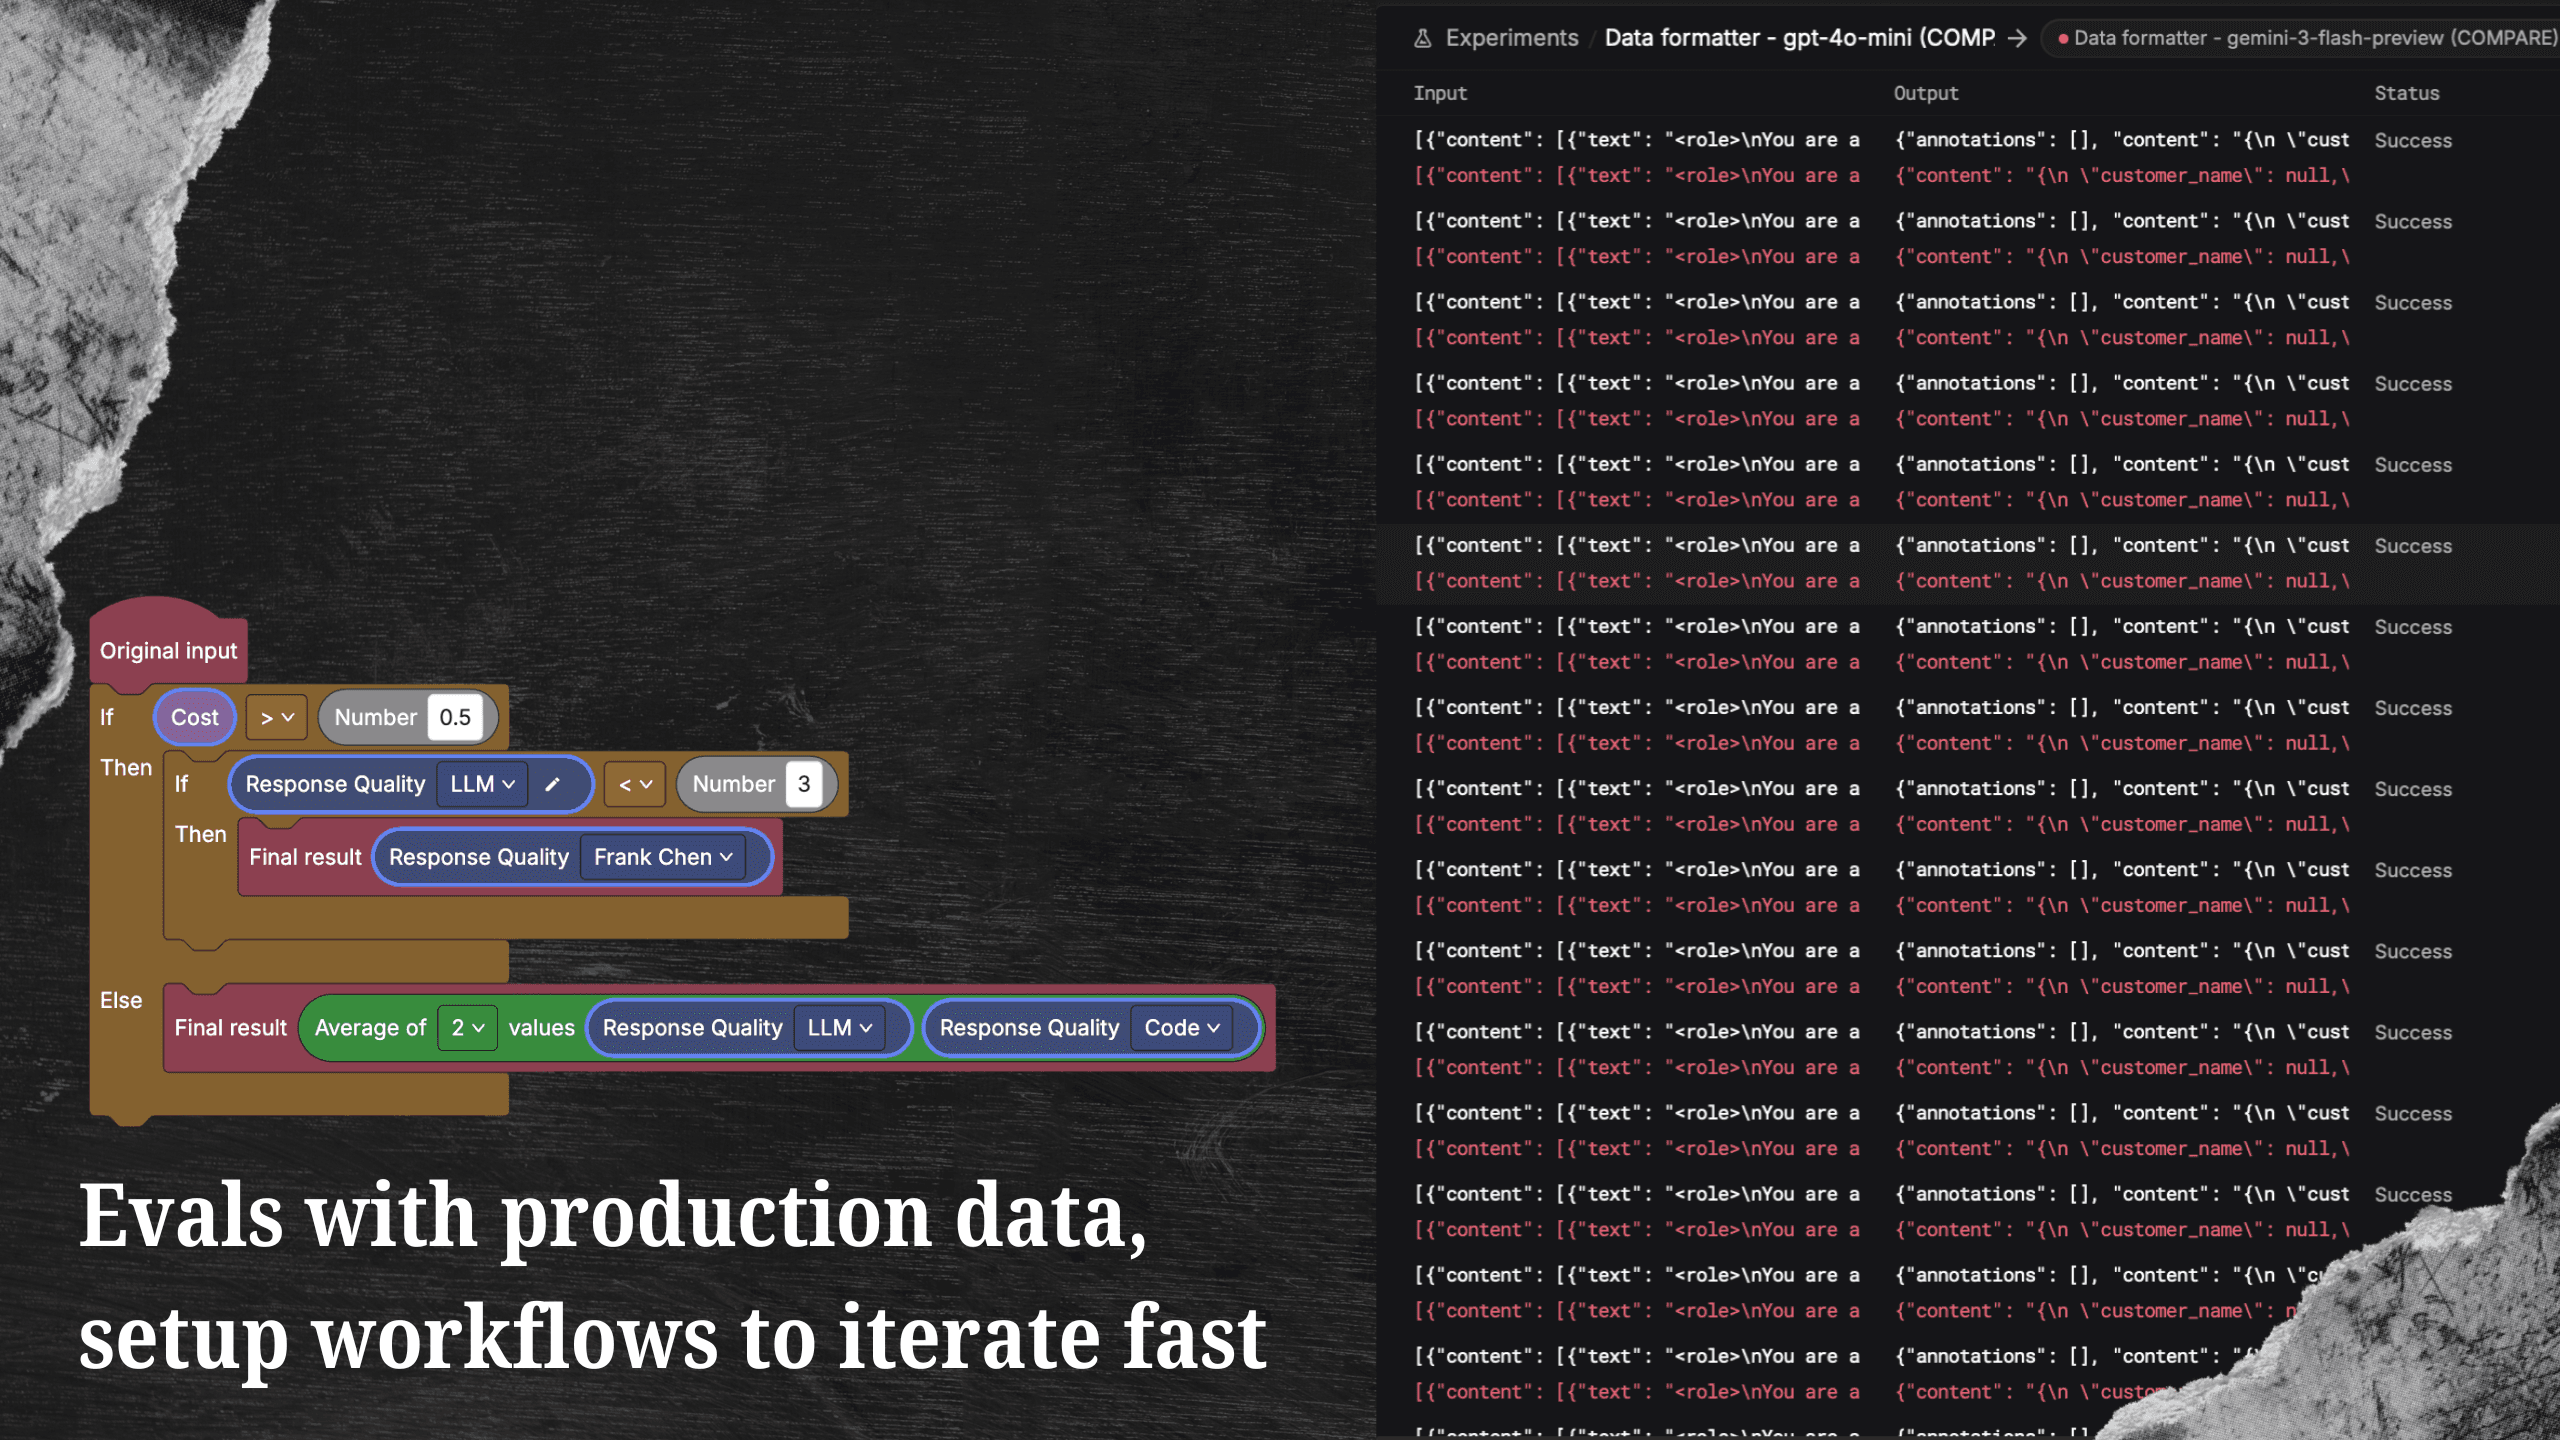
Launch Week Day 2: Evals 2.0
Respan Evals gives you a repeatable pipeline to test prompts and models against real data, score them with LLM judges, code checks, and human review, then compare results side by side.
Frank Chen · April 21, 2026
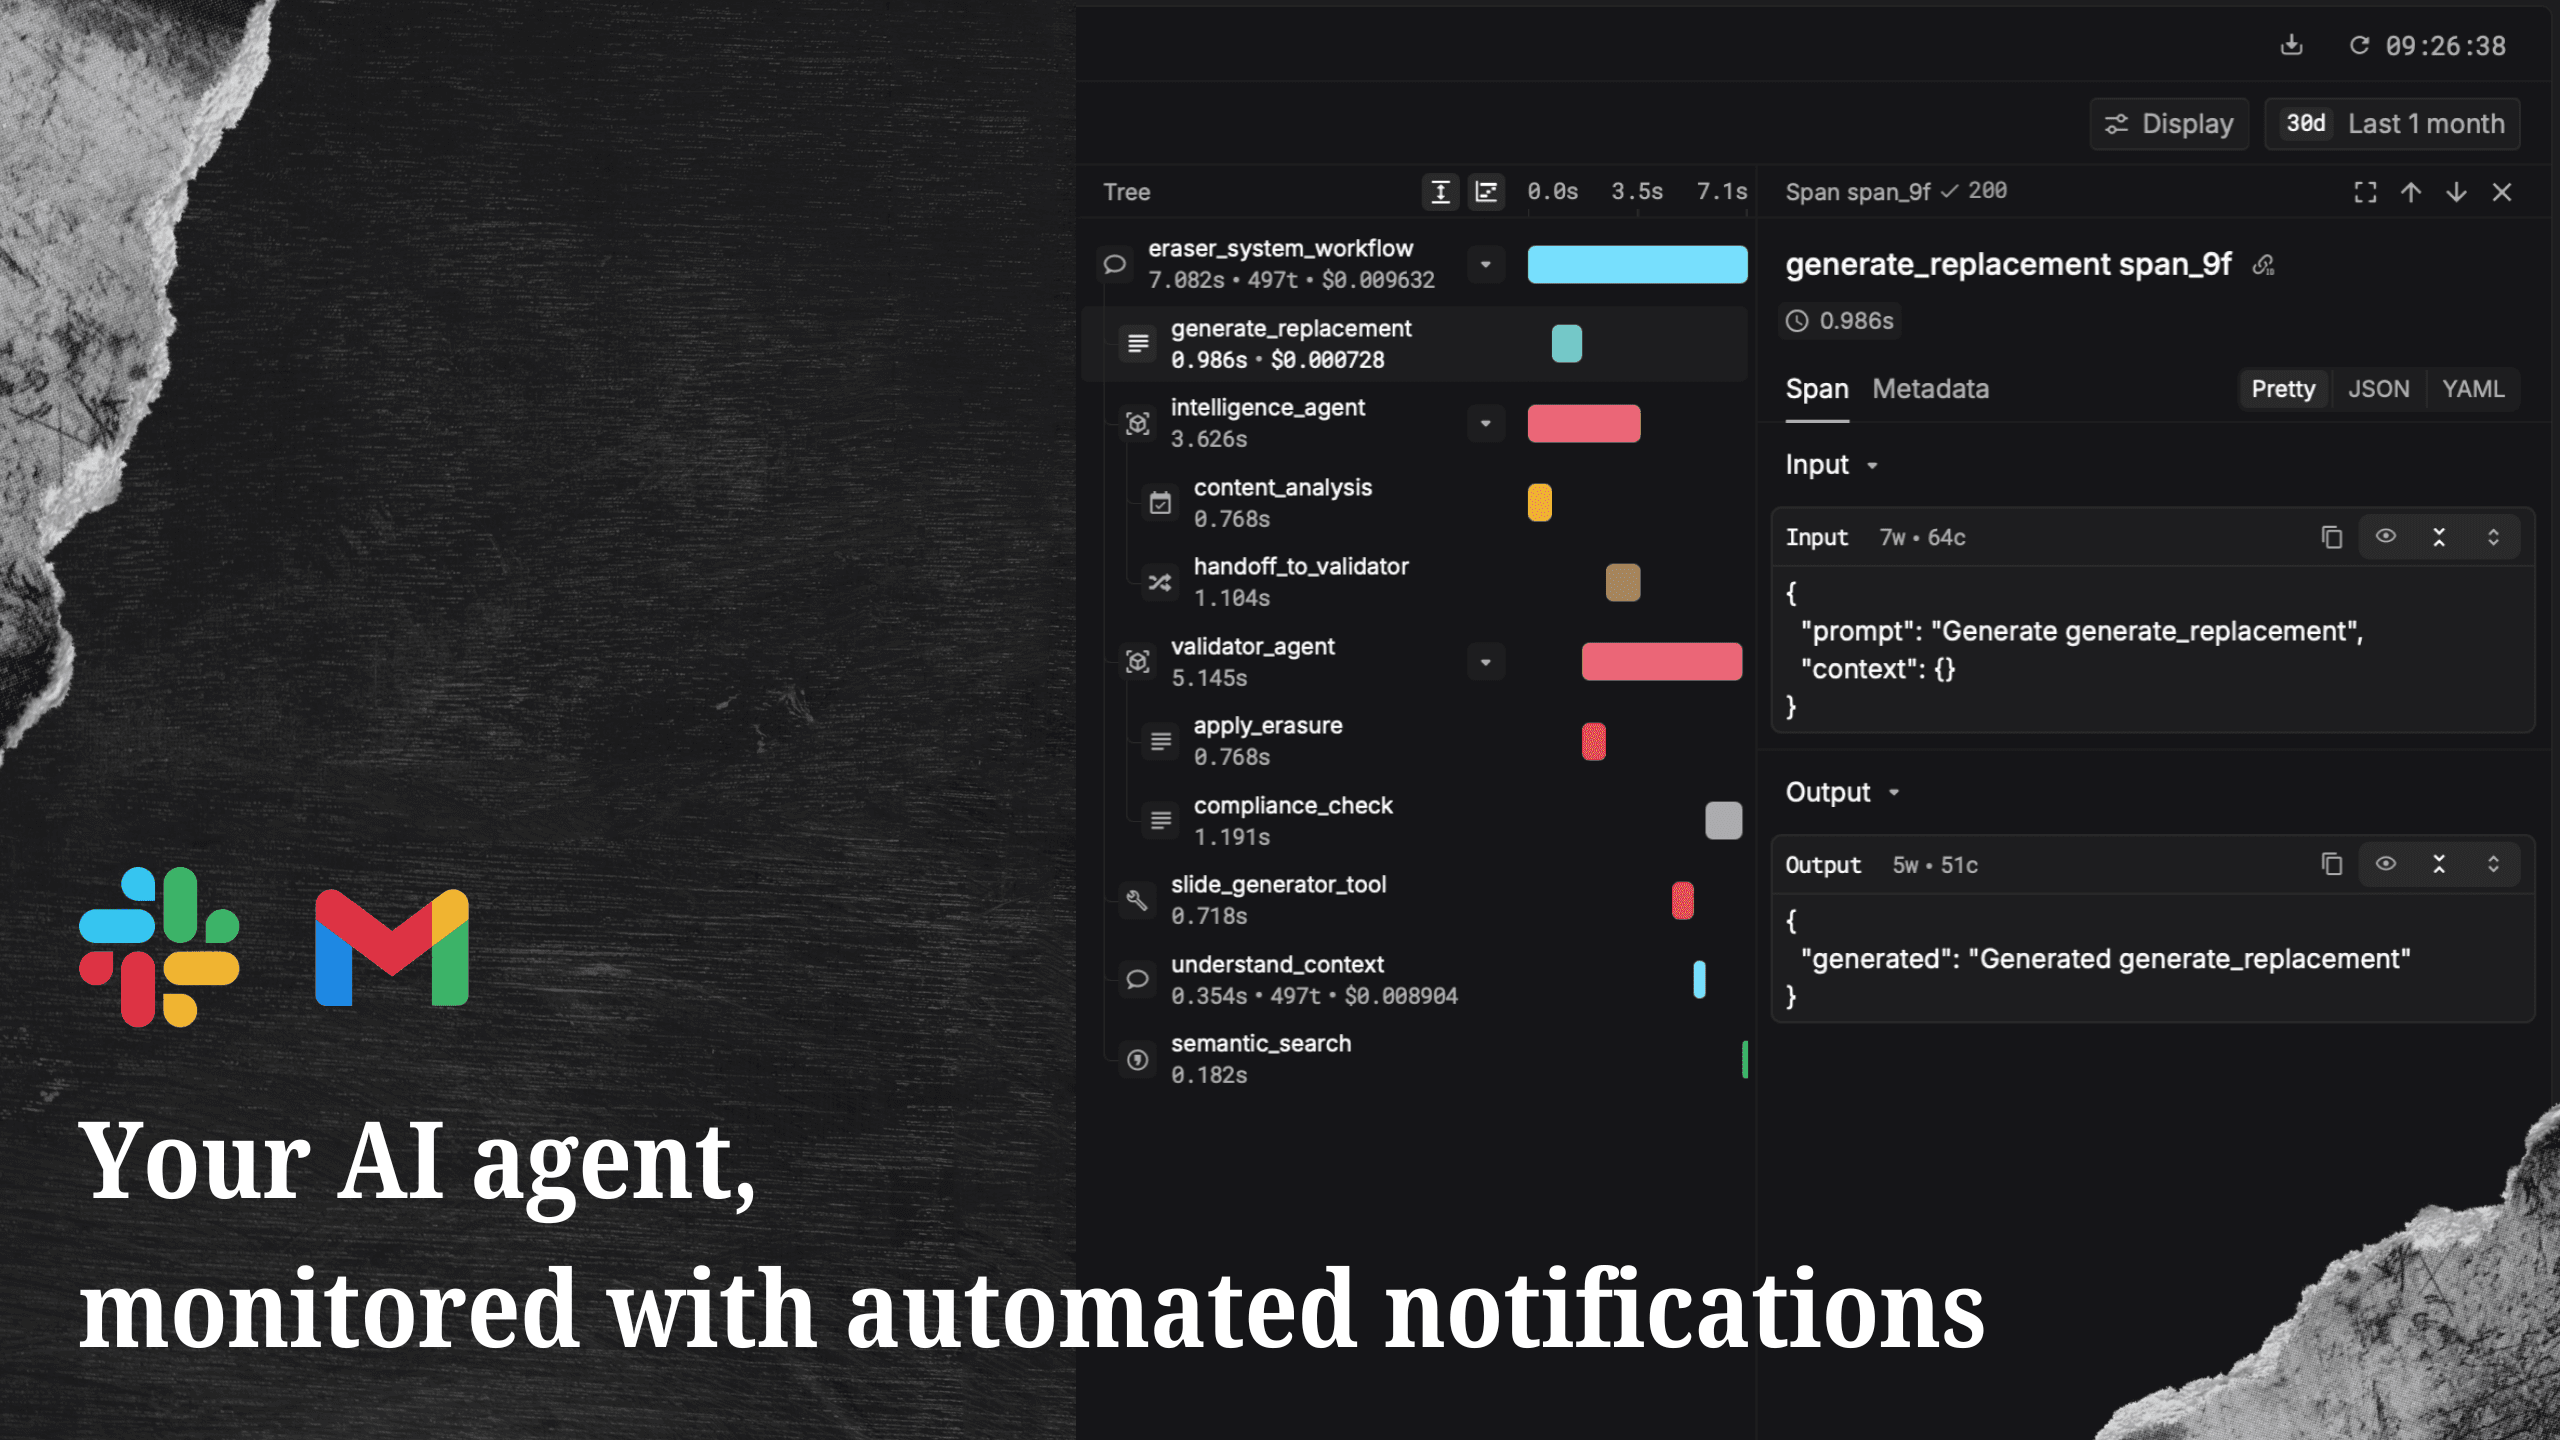
Launch Week Day 1: Monitors
Respan Monitors automatically track your LLM application metrics and alert you when things go wrong. Error rate spikes, cost overruns, latency regressions, and more.
Frank Chen · April 20, 2026
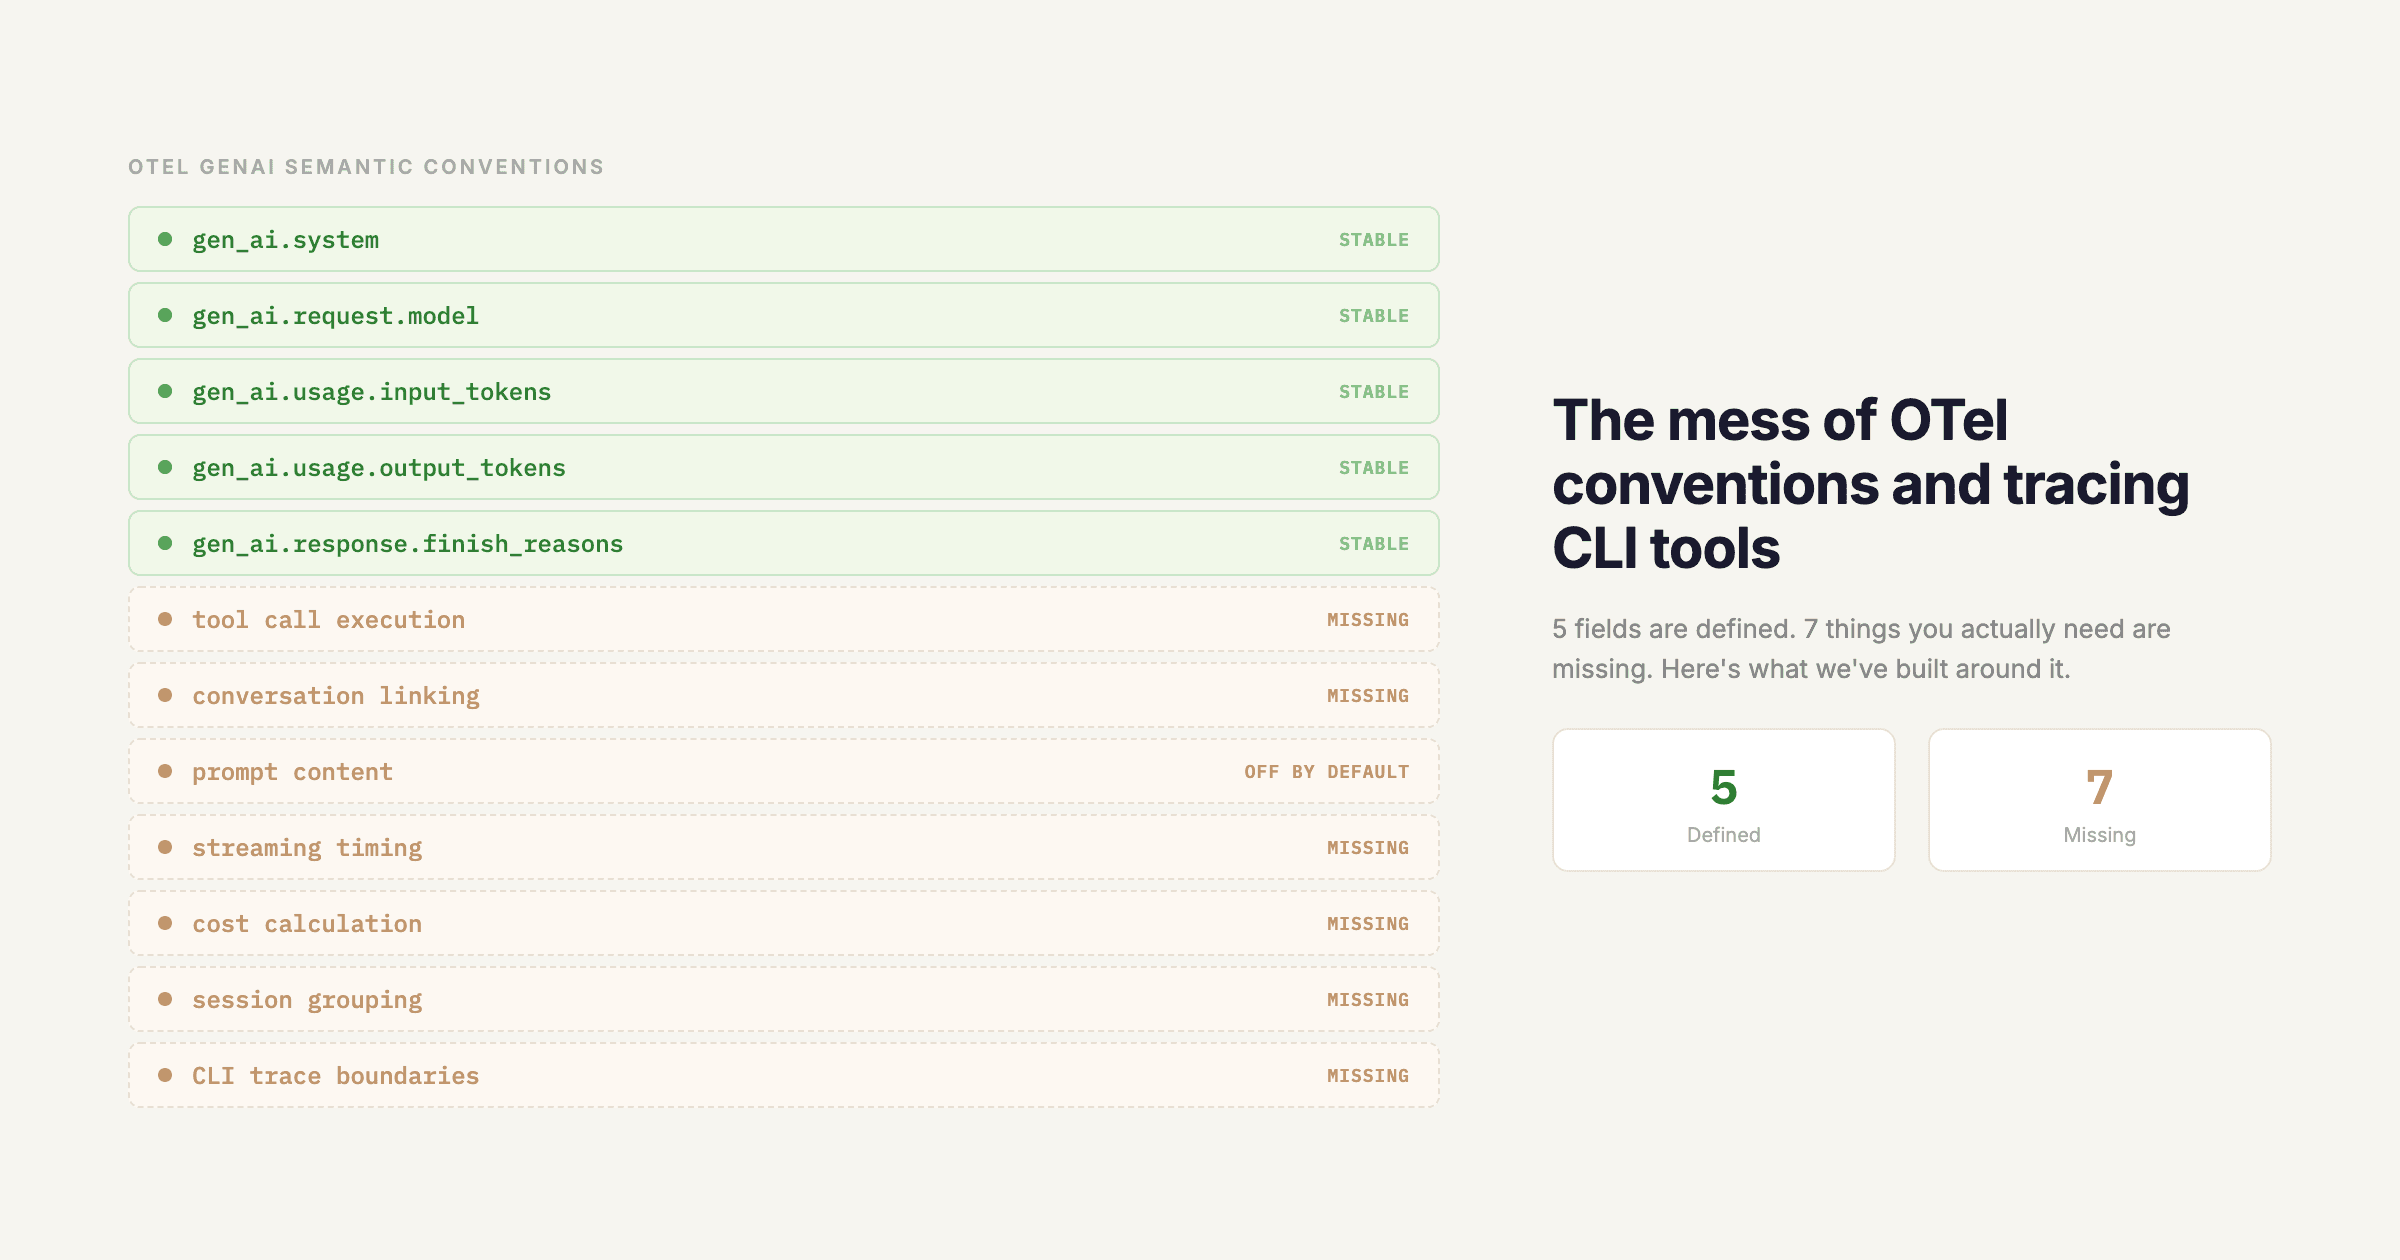
The mess of OTel semantic conventions and why tracing CLI tools is still painful
An honest look at the state of OpenTelemetry semantic conventions for LLM applications, the specific challenges of tracing CLI-based AI tools, and practical workarounds that actually work in production.
Hendrix Liu · April 10, 2026
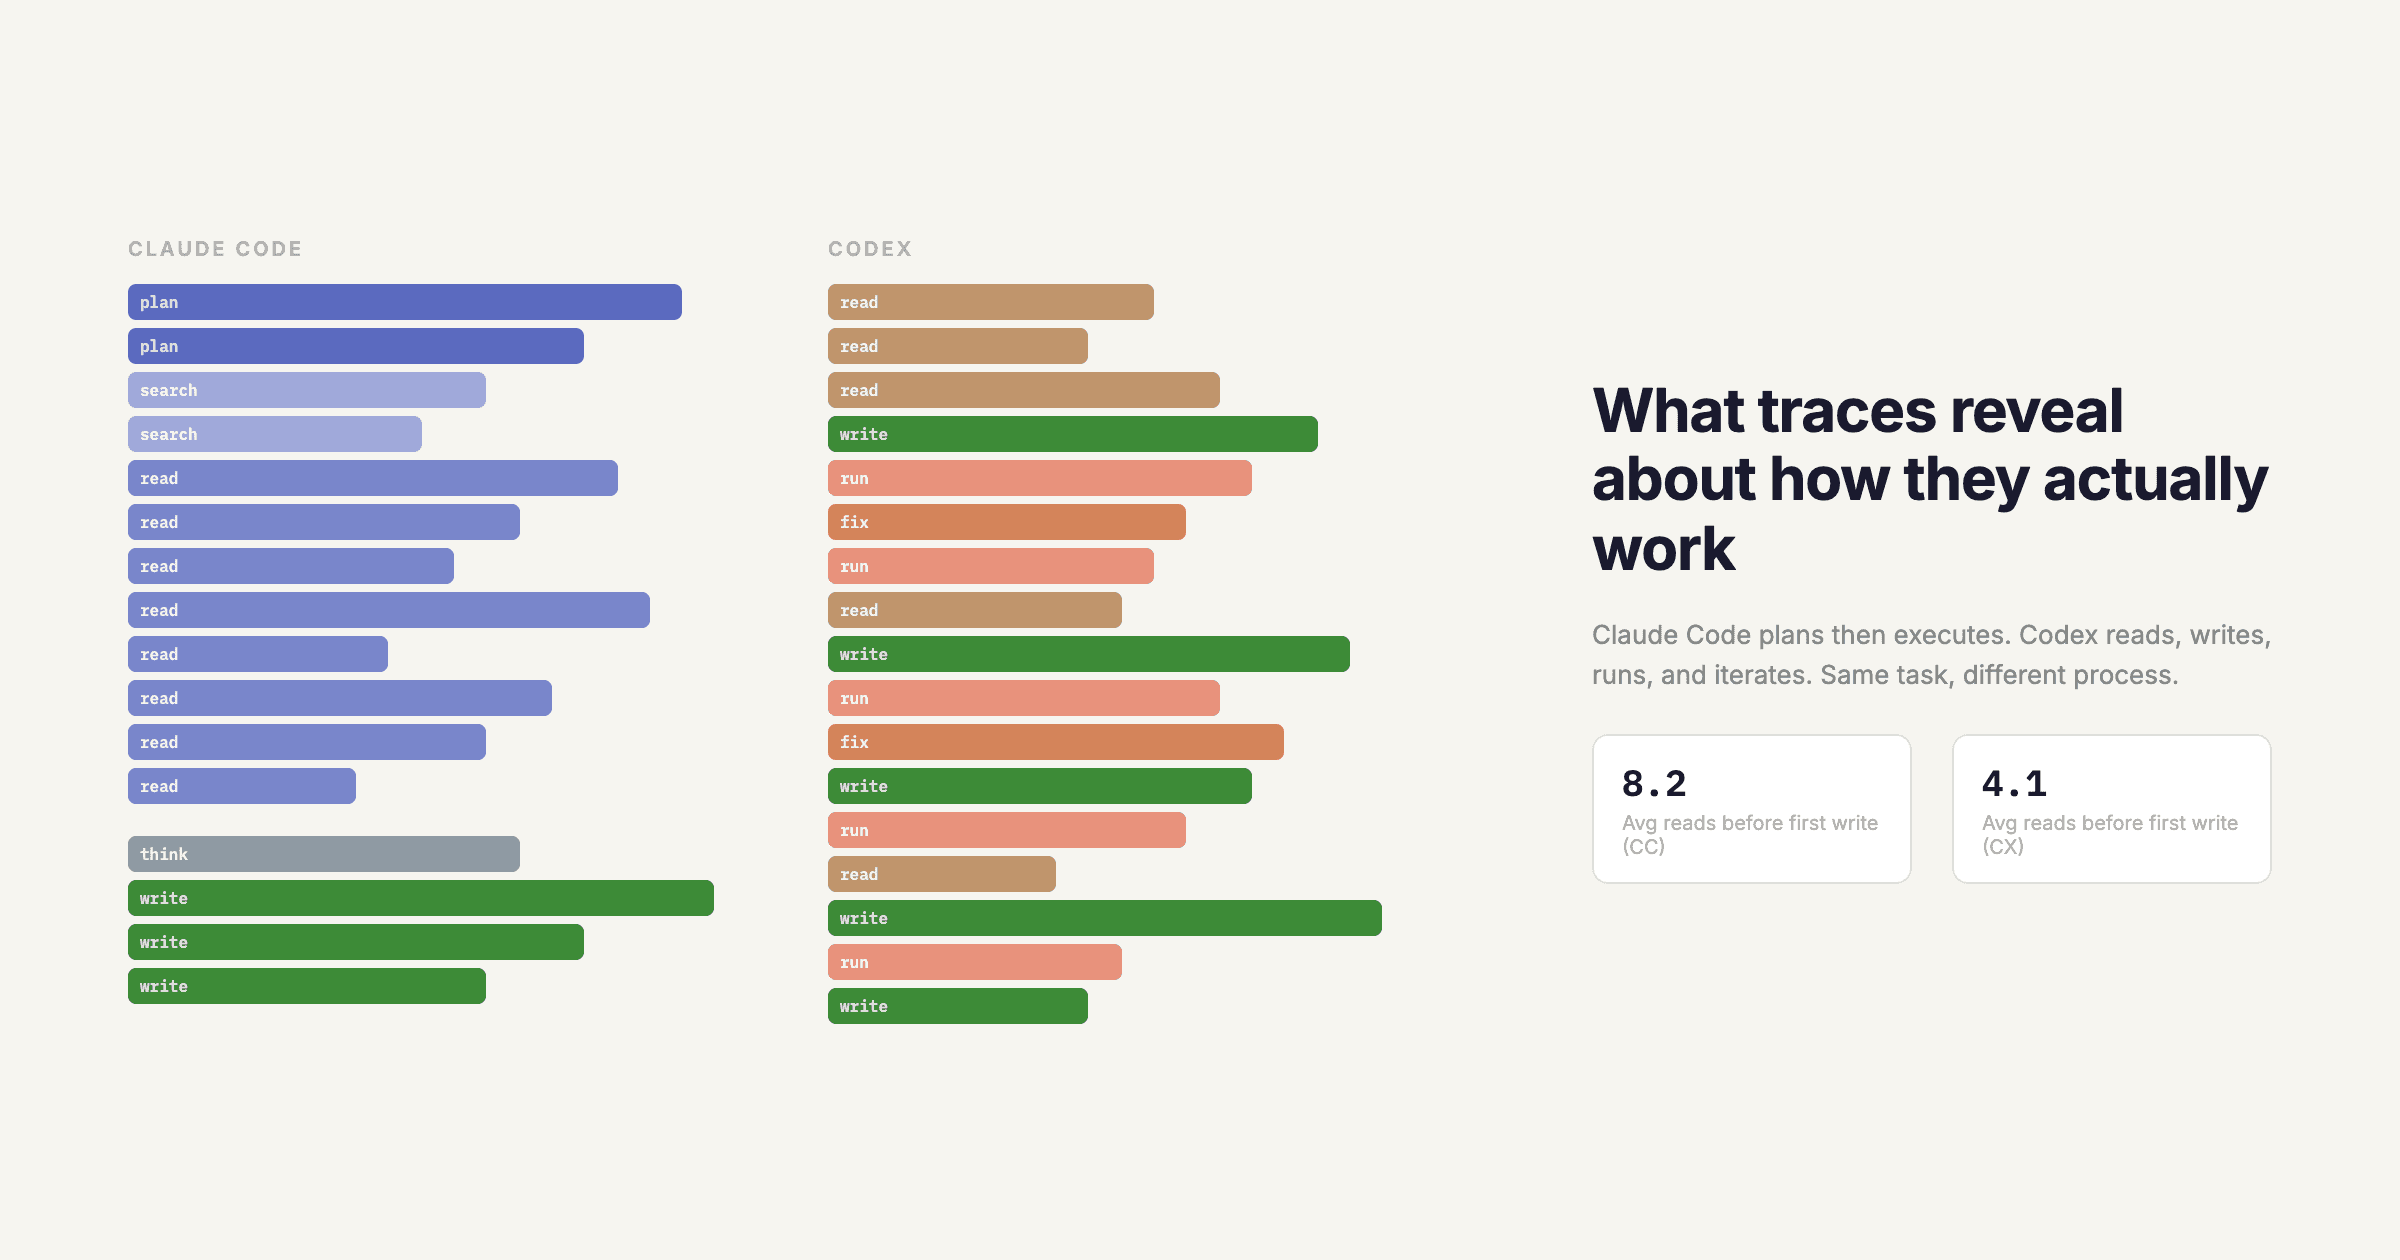
Tracing Claude Code and Codex: How Each Agent Plans and Recovers
Respan traced Claude Code and Codex CLI across 30 tasks to see how each agent plans, calls tools, recovers from errors, and spends tokens.
Frank Chen · April 9, 2026
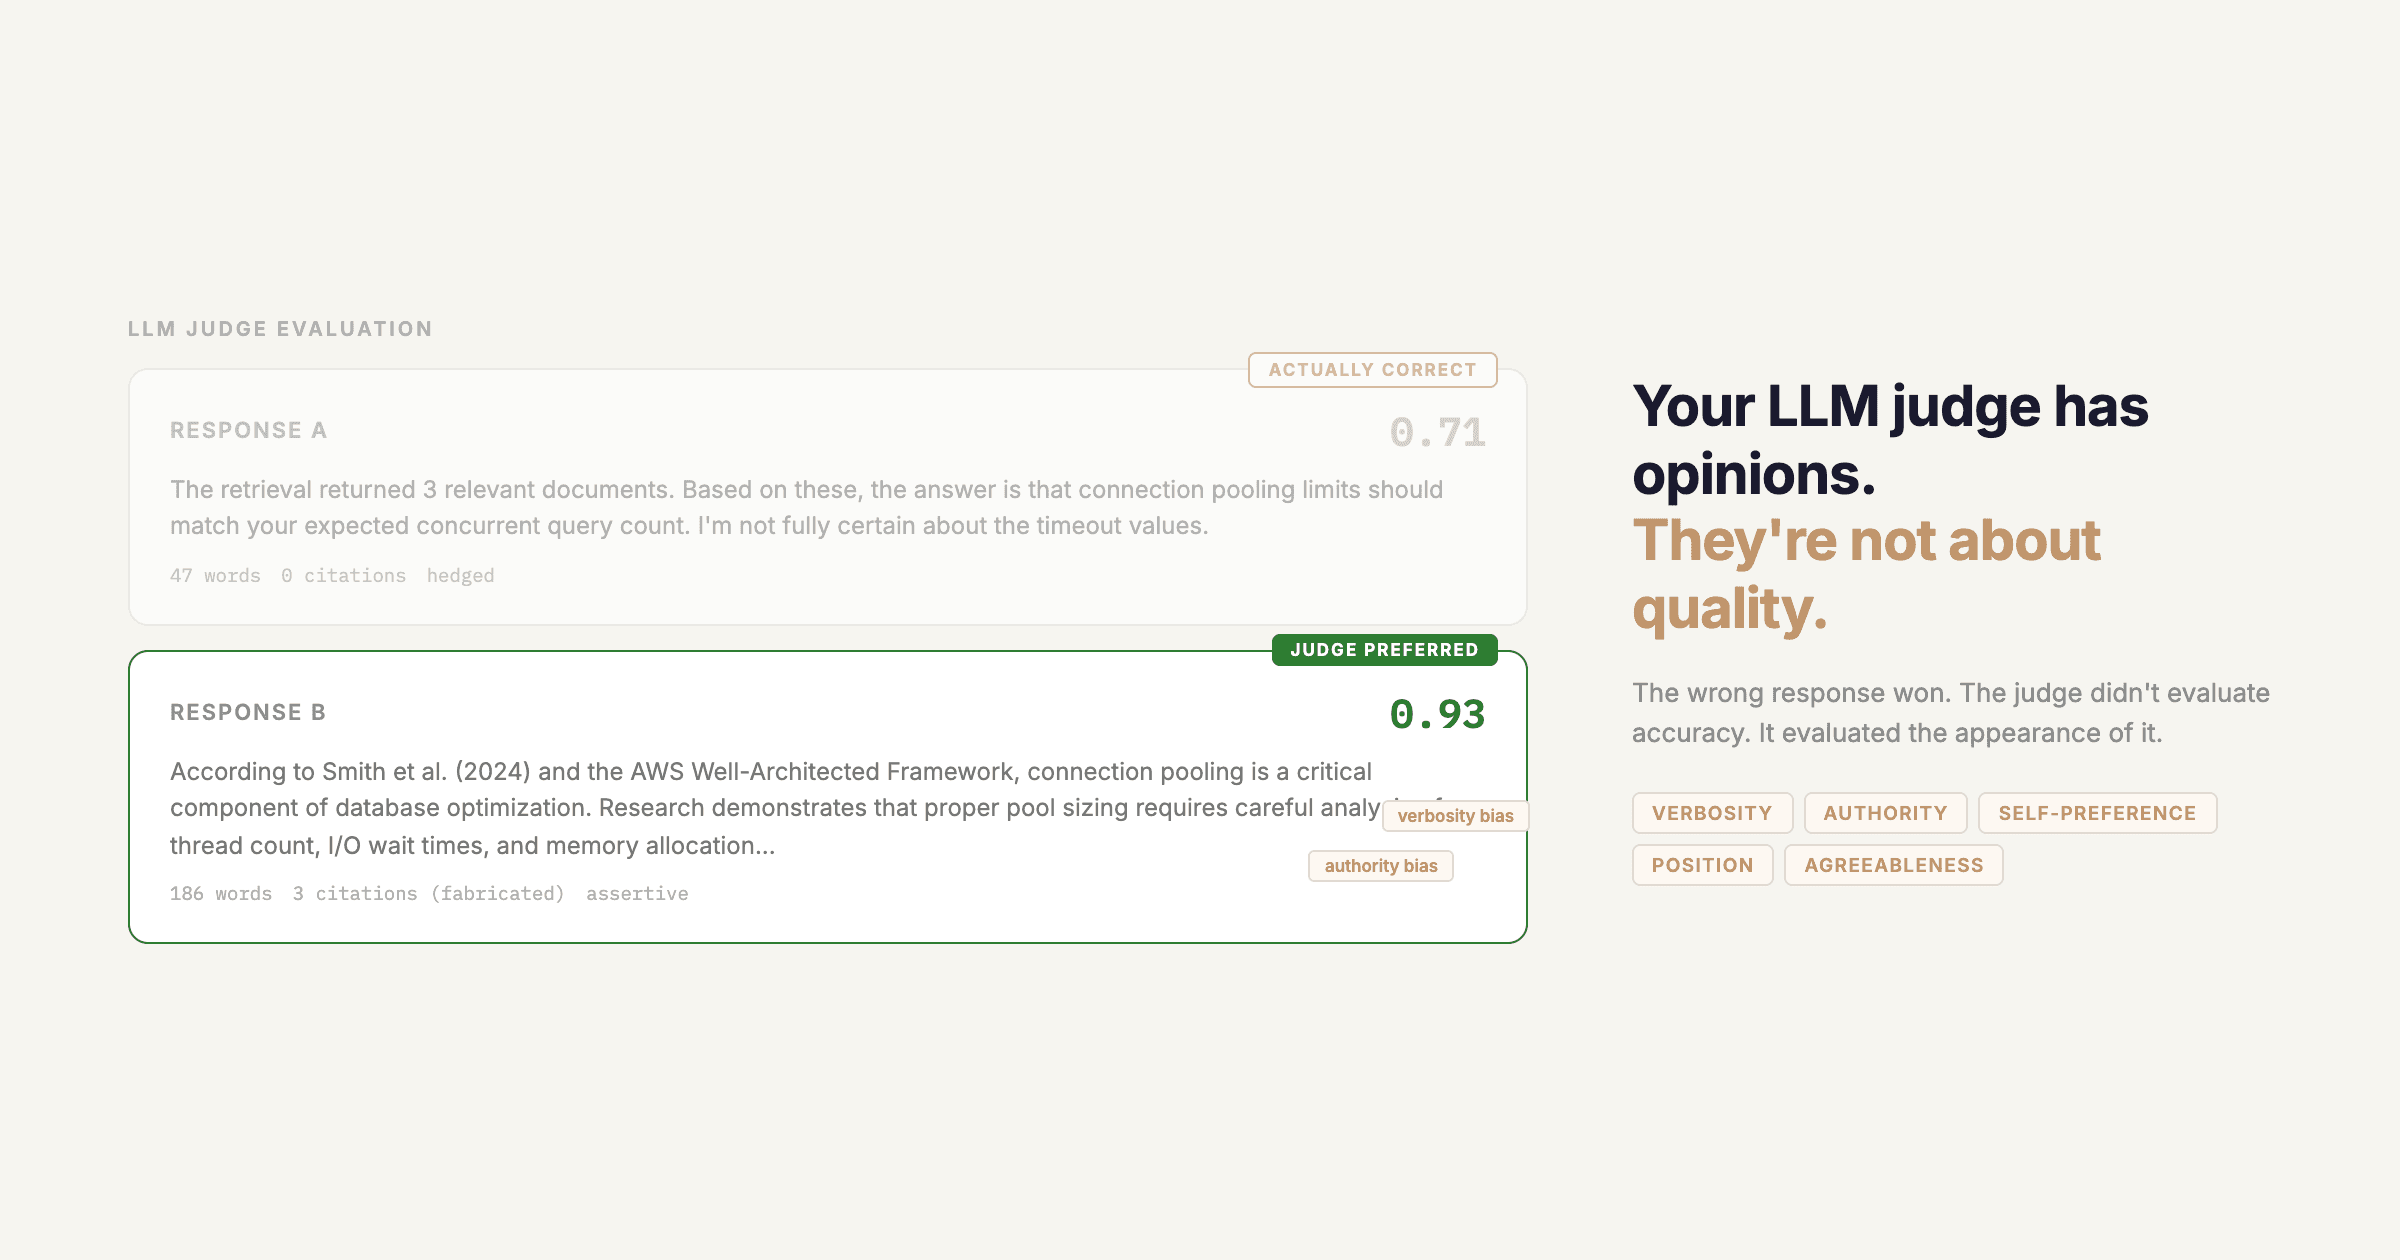
Your LLM Judge Has Opinions. They're Not About Quality.
A deep dive into the systematic biases in LLM-as-a-judge evaluation, including self-preference, verbosity, authority, agreeableness, and position bias, and how to design experiments that produce conclusions you can actually trust.
Frank Chen · April 8, 2026
The 25 ways your LLM app is failing (and why you can't see most of them)
A catalog of 25 LLM failure modes in production: loud failures you can catch, silent failures that hide in plain sight, and slow failures that only reveal themselves in hindsight.
Frank Chen · April 7, 2026
Announcing our $5M seed round led by Gradient Ventures
Respan announces a $5M seed round led by Gradient Ventures with participation from Y Combinator. We're building the first proactive AI observability platform that closes the loop from evals to production.
Respan · March 18, 2026
How AI agents actually work: a mental model for builders
Learn the mental model behind AI agents, from graph theory to finite state machines to LLM-driven transitions. A practical framework for designing, debugging, and communicating agent architecture.
Frank Chen · March 9, 2026
How Retell AI runs 1M+ hourly LLM calls for voice AI agents on Respan
Retell AI ingests 1M+ LLM calls per hour on Respan, with full per-call thread visibility, metadata-indexed exports for evals, and real-time alerts on stream timeouts and fallbacks.
Retell AI · February 24, 2026
How Mem0 built a 99.99% reliable memory layer for AI agents on Respan
Mem0 runs hundreds of millions of LLM calls a day across multiple providers on Respan, with 99.99% reliability, end-to-end traces, and per-user cost visibility.
Mem0 · February 21, 2026
Announcing our new brand: Respan
AI agents are becoming real software, but observability and eval tools haven't kept up. Respan is the first proactive LLM observability platform that closes the loop from agent observability to evaluation to iteration.
Respan · February 20, 2026
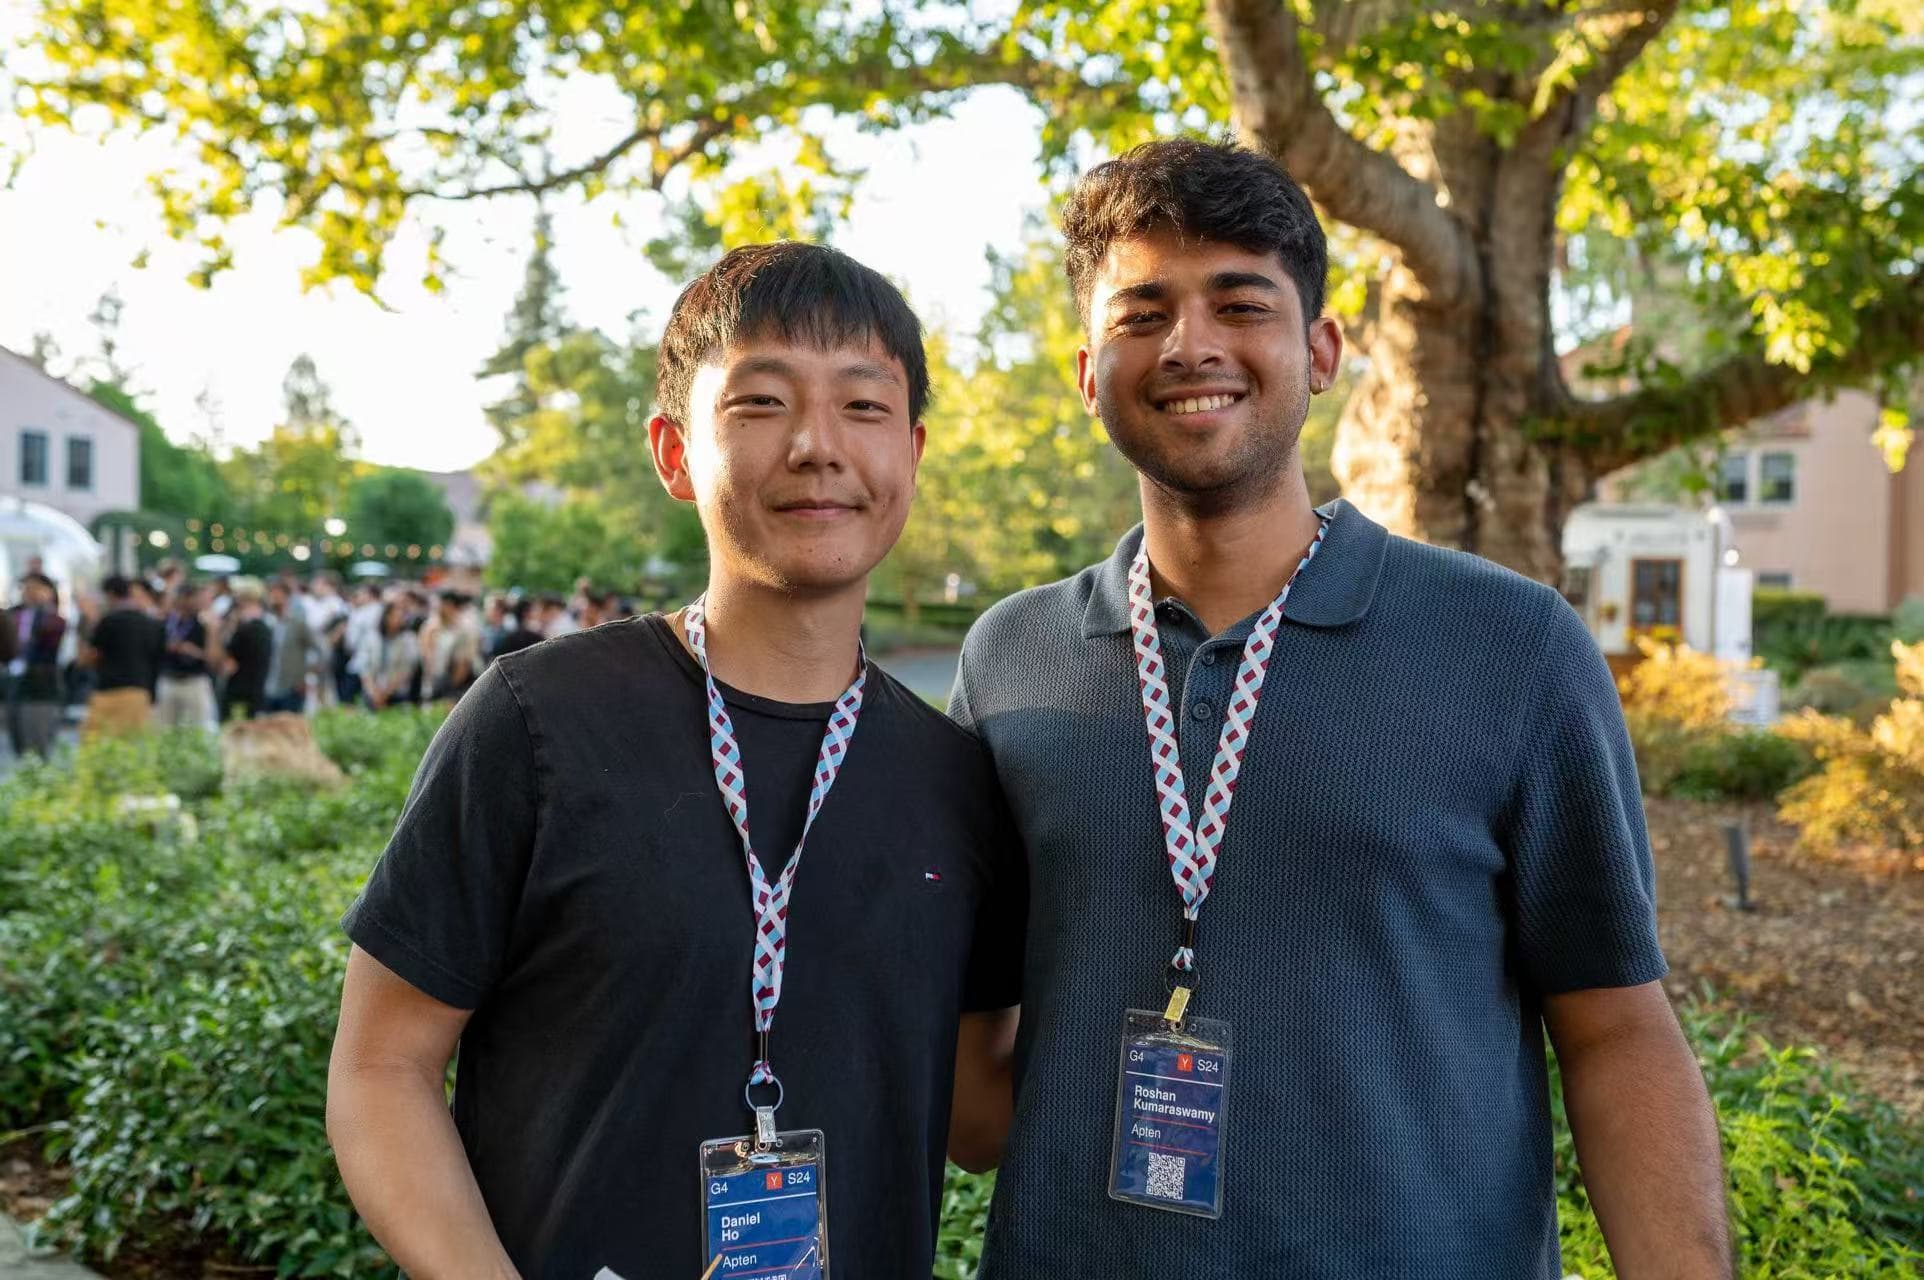
How Apten debugs and deploys LLM models 10x faster with Respan
Apten uses Respan to debug and deploy LLM-powered SMS, voice, and email agents 10x faster, processing 150,000+ requests per day with full visibility.
Apten · February 19, 2026
How to get consistent and reproducible LLM outputs (OpenAI, Gemini, Claude, vLLM...)
A practical guide to achieving reproducible LLM outputs across OpenAI, Gemini, Claude, and vLLM, covering sampling, batching, numeric drift, and batch invariance.
Frank Chen · February 19, 2026
GPT-5 mini vs Gemini 3 Flash Preview vs Claude 4.5 Haiku
A practical comparison of GPT-5 mini, Gemini 3.0 Flash Preview, and Claude 4.5 Haiku for production: pricing, context windows, rate limits, and reliability.
Frank Chen · February 17, 2026
How to Set Up OpenTelemetry for LLM Apps
Learn how to set up OpenTelemetry for LLM observability across Haystack, Vercel AI SDK, and LiteLLM. Compare manual OTel setup vs automated tracing with Keywords AI for production AI applications.
Frank Chen · January 26, 2026