The only AI gateway with built-in observability and evals.
Unified router or provider passthrough for 1,000+ models, with failover, response caching, warn/block limits, and metadata on every logged request.
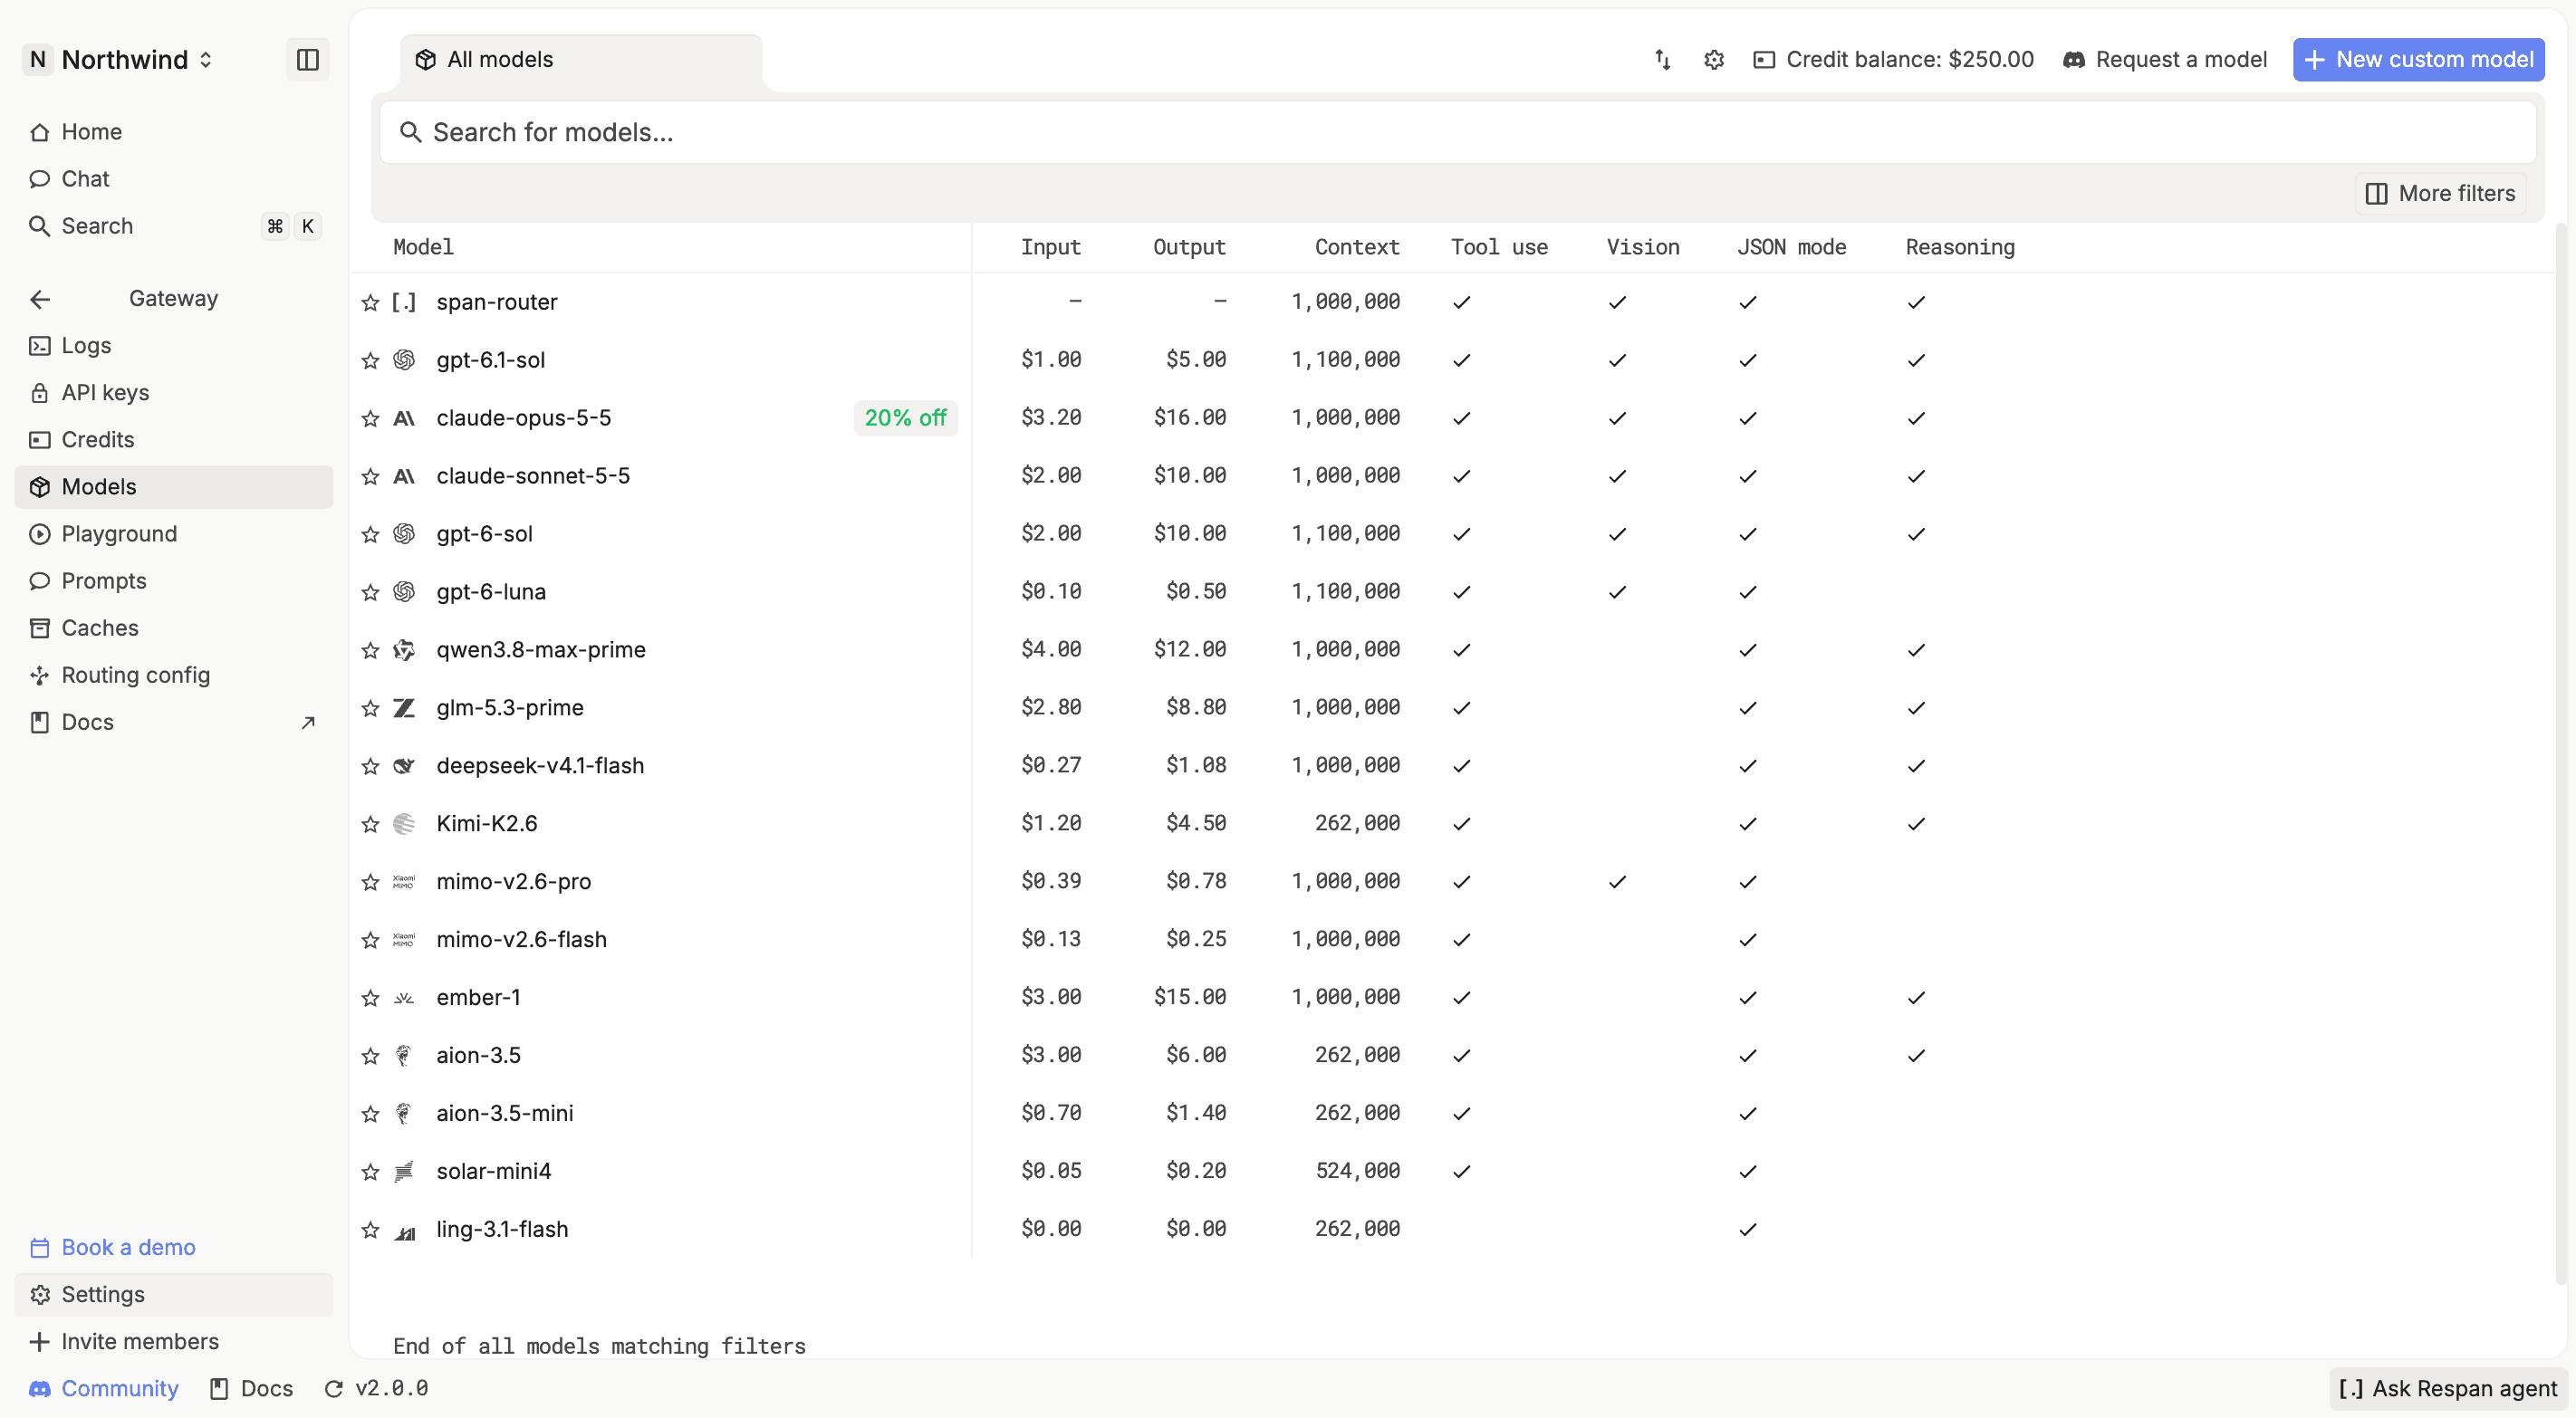
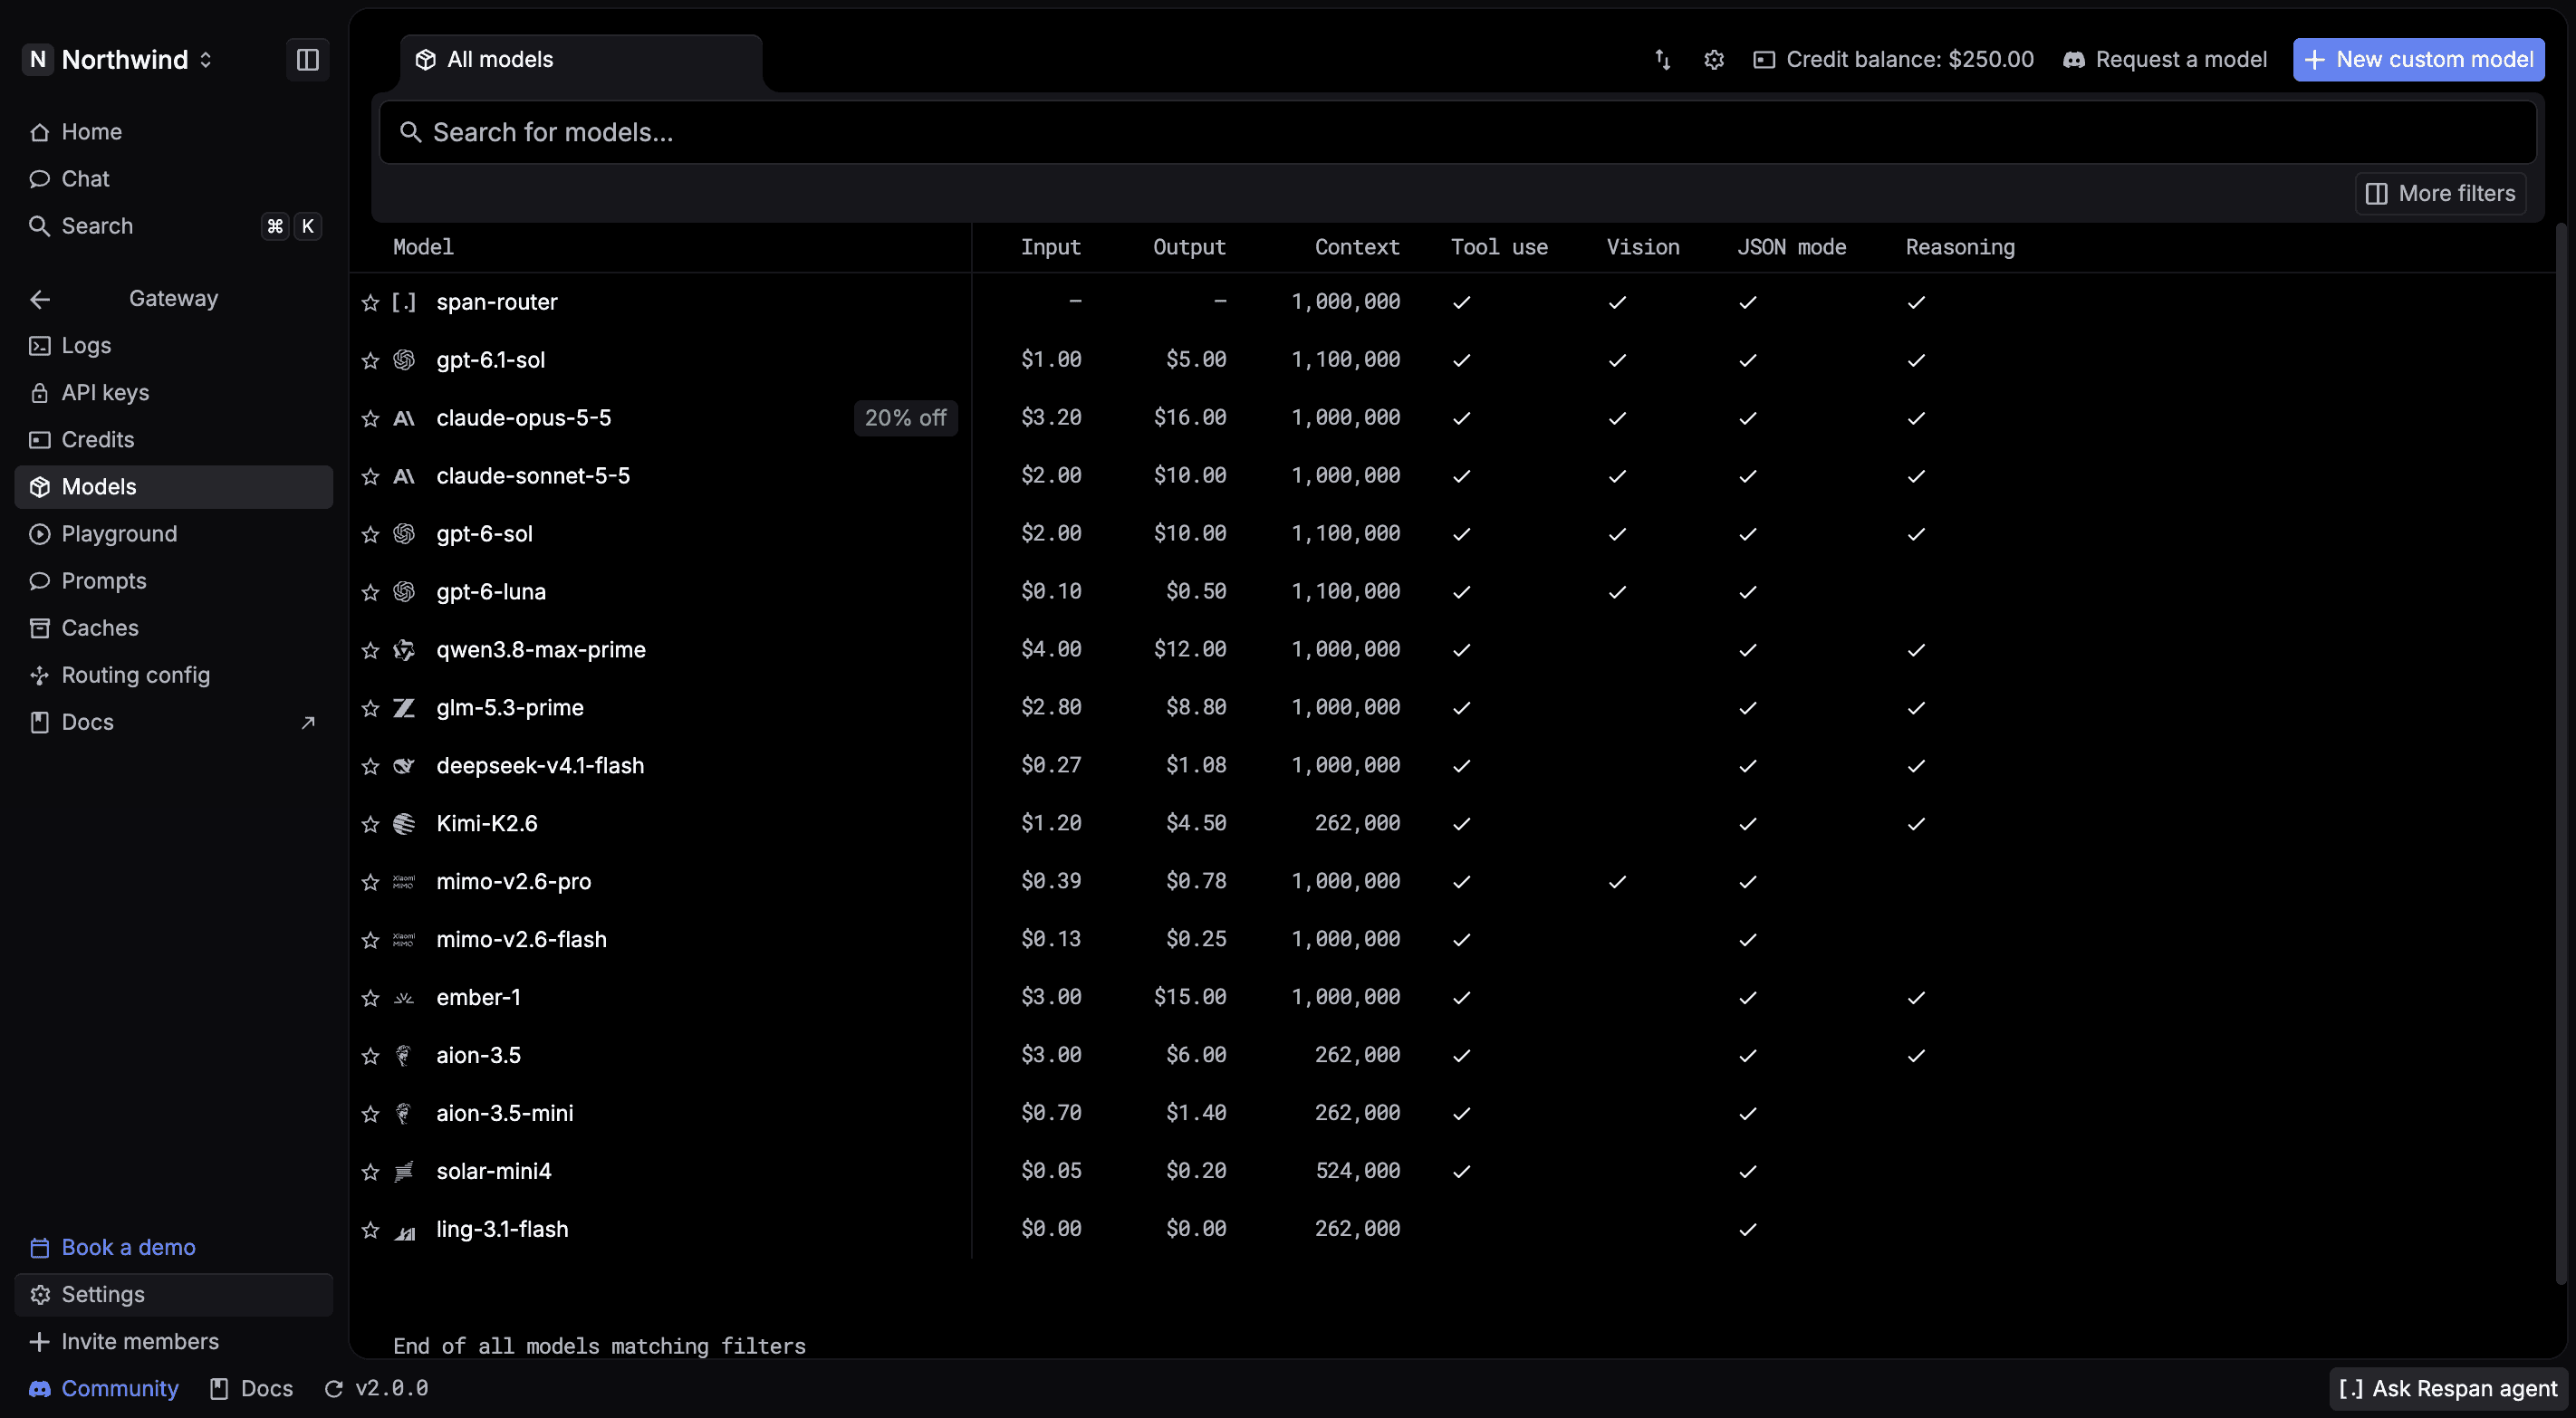
Reach every model, and stay up.
Point the SDK you already use at one endpoint to reach 1,000+ models, with automatic fallbacks, response caching, and spend limits built in.
One API for every model
Send every request to one endpoint, reach 1,000+ models across every major provider, and switch between them by changing a single word.
One model fails, the next takes over
List the models to fall back to, and Respan moves to the next the moment one errors or rate-limits, so an outage never takes you down.
Repeat requests served from cache
Cache a request and its response, then serve the same call again instantly, cutting the cost and latency of every repeat to nothing.
Budgets and limits at every scope
Set budgets and rate limits per key, per customer, or org-wide, get warned as you near them, and block requests before spend runs away.
You own every integration.
Call each provider directly and you inherit its SDK, quota, outages, and bill, until one endpoint sits in front of them all.
A new model means new code
Every provider ships its own SDK and request shape, so trying a different model turns into a refactor instead of a one-line change.
One provider goes down, so do you
A single upstream error or rate limit lands straight on your users, because there is no second model standing by to take the request.
Rate limits you cannot route around
Traffic sits on one account's quota, so a busy hour throttles everyone at once, with no second key or region to spread it across.
The same answer paid for twice
Identical prompts go upstream again and again, and you pay full price and full latency for a response you already had minutes ago.
Spend you only see on the invoice
Nothing warns you as the bill climbs and nothing stops a request once it passes the cap, so a runaway loop is a month-end surprise.
Every provider in its own dashboard
Usage lives in one console per provider, so there is no single view of a request and no way to split cost by customer or feature.
Start routing with one request.
Point the SDK you already use at one endpoint and switch providers with a model slug, or keep a native SDK on a passthrough URL.
from openai import OpenAI client = OpenAI( base_url="https://api.respan.ai/api/", api_key="YOUR_RESPAN_API_KEY",) response = client.chat.completions.create( model="claude-opus-4-8", messages=[{"role": "user", "content": "Hello!"}], extra_body={ "fallback_models": ["gpt-5.4", "gemini-3-flash"], "cache_enabled": True, "customer_identifier": "user_123", "metadata": {"feature": "chatbot", "env": "prod"}, })from openai import OpenAI client = OpenAI( base_url="https://api.respan.ai/api/", api_key="YOUR_RESPAN_API_KEY",) response = client.chat.completions.create( model="claude-opus-4-8", messages=[{"role": "user", "content": "Hello!"}], extra_body={ "fallback_models": ["gpt-5.4", "gemini-3-flash"], "cache_enabled": True, "customer_identifier": "user_123", "metadata": {"feature": "chatbot", "env": "prod"}, })The AI observability platform behind 80 trillion+ tokens.
Loved by world-class founders, engineers, and product teams.
“Imagine jumping to a log immediately after every LLM call. This is the dream for debugging.”
Daniel Wolf
Product Lead, AlphaSense
“We scaled from 5M to 500M+ monthly API calls quickly. Respan gave us the debugging layer to resolve production issues 10x faster.”
Read how Retell builds next-gen voice agents that scale->Zexia Zhang
CTO, Retell AI
“Respan legit has some of the best UX/DX I’ve ever seen in my life. I truly don’t think I’ve ever integrated a product that was as easy.”
Rahul Behal
Co-founder, Gumloop
“This one felt pretty nice.”
Fabian Hedin
CTO, Lovable
“Such a no brainer choice over LangSmith or anything else and super easy to set up.”
Andy Wang
CEO, Finta
“Respan has been key in helping us scale to trillions of tokens reliably with real-time observability.”
Read how Mem0 builds reliable self-improving AI memory layer->Deshraj Yadav
CTO, Mem0
“Great product - really love the metrics dashboard.”
Esha Dinne
CTO, Giga
Certified where it counts.
Built to meet the security and privacy standards that enterprise and healthcare teams require.
ISO 27001
The internationally recognized standard for information security management.
SOC 2
Secure, compliant management of your data across all of our systems.
GDPR
Operated under GDPR, the world's strictest standard for data privacy.
HIPAA
HIPAA compliant, with a BAA available for healthcare teams.
Works with your entire stack
Use Respan with your favorite frameworks and tools.

